The following notes are from the course Asset Management: Advanced Investments, taught at the University of Zurich (UZH) by Professor Thorsten Hens and Alexandre Ziegler.
Feel free to reach out to me with any comments, clarifications, or corrections.
Index
- Introduction to Asset Management: Asset Allocation, Hedging and Performance Measures
- Strategy Development: Sources of Returns, Return Calculations, Performance Measurement and Timing Ability
- Principles of Strategy Development: Statistical Significance, Overfitting, Biases and Transaction Costs
- Constant-Allocation, Timing and Selection Strategies: Risk Premium Estimation and Predictive Models
- Combining Strategies and Implementation: Portfolio Weights, Leverage, Short Selling and Levered ETFs
- Equity Risk Premium and Return Predictability: Valuation Ratios, Dividend Yield and the Term Premium
- Volatility, News Sentiment and Seasonality: Further Predictors of Equity Returns
- The Cross-Section of Expected Returns
- Bonds, the Expectation Hypothesis and Bond Risk Premium
- Bond Predictability and the Cross-Section of Bond Returns
Introduction to Asset Management: Asset Allocation, Hedging and Performance Measures
Asset management is about investing in assets to achieve certain goals subject to restrictions.
Wealth management determines the goals and restrictions.
Risk management makes sure the restrictions are satisfied.
- SAA (Strategic Asset Allocation): allocation to asset classes that should be followed in the long term. Possible approaches include:
- Mean-variance analysis
- Mean-downside-risk analysis (Ortec), which focuses on an investment's expected return (the mean) relative to its potential losses, ignoring positive gains entirely.
- TAA (Tactical Asset Allocation): tactical deviations from the SAA on a short-term (monthly) basis. Possible approaches include:
- Passive rebalancing on an event-driven or time-frequency basis
- Quantitative analysis (fundamental monetary macroeconomic (FMM) view)
- Quantitative analysis based on regression
- Rank-based
- IAA (Investment Asset Allocation): implementation of the TAA through investments
- Hedging: an overlay on the SAA to satisfy restrictions and risk constraints.
- FX hedging: the standard rule is to:
- hedge nominal assets
- partially hedge real assets.
- Example: typically, FX hedging for a CHF investor reduces volatility while preserving the mean return.
- Tail-risk hedging: used when the payoff function is asymmetric.
- FX hedging: the standard rule is to:
Different types of asset allocation have different explanatory power for observed returns:
- SAA explains 75% of observed returns
- TAA explains 20%
- IAA explains 5%
Furthermore, they differ in their quantitative/qualitative approaches: from SAA (the most qualitative), we move through TAA and IAA to pure trading (the most quantitative).
Performance Measures
We define the arithmetic average of returns as:
In contrast, the geometric average return is:
The time-weighted return (TWR) measures the average return for a fixed amount over :
In contrast, the money-weighted return (MWR), also known as the internal rate of return (IRR), measures the average return when variable amounts are invested over . It is computed by solving for the rate that satisfies:
Strategy Development: Sources of Returns, Return Calculations, Performance Measurement and Timing Ability
Finding ideas is the hard part of strategy development. Conceptually, one can see returns as coming from three sources:
- asset classes
- strategy styles (carry, value, trend, volatility)
- underlying risk factors
For example, here are three sources of returns for some common strategies:
- constant-allocation strategies: earn risk premia on asset classes over time. The allocation depends on the (unconditional) risk premium, the level of risk, and the timing of losses.
- timing strategies: rotate among asset classes, with position sizes depending on conditional risk premia and estimates.
- selection strategies: take long and short positions within an asset class. They usually do not target risk premia, but returns provided by strategy styles.
Testing the strategy is an essential part of the process. Ideally, you should know what to test before downloading the data. Common sources of data are:
- general data sources (Bloomberg, Datastream, Yahoo Finance)
- specialized sources (CRSP, Compustat, OptionMetrics)
It is important to be aware of biases and to make sure that dividends and interest are accounted for.
Returns
We distinguish ordinary returns and log returns . If an asset has price at time and pays interest or dividends (net of tax, for simplicity) , the ordinary return is:
Log returns are instead given by:
Suppose we invest an amount at and earn or each period. After periods, we have:
We can also write cumulative returns and :
(Note that log returns are time-additive, whereas ordinary returns are not.)
Furthermore, for ordinary returns, the average return per period is the geometric mean:
For log returns, the average return per period is the arithmetic mean:
But when should we consider ordinary versus log returns?
- For realized returns:
- If the arithmetic average ordinary return is zero, you lose money unless every return is zero.
- If the geometric average ordinary return is zero, you break even.
- If the arithmetic average log return is zero, you break even.
For expected returns (assuming independent returns):
- For ordinary returns, if the expected one-period return is zero, then:
- over a single period, on average, you break even;
- over multiple periods, on average, you break even.
- For log returns, if the expected one-period log return is zero, then:
- over a single period, on average, you make money;
- the same applies over multiple periods.
Consider now a series of monthly returns with periods in a year. The average annual return solves
The average annual log return is instead:
Suppose now that we want to decompose the overall return of the portfolio into the returns of assets, , with weight in the portfolio.
The portfolio returns in period are then:
(Note that ordinary returns aggregate in the cross section, but log returns do not; therefore):
- if you want to compute the one-period return of a portfolio of assets, it is easier to work with ordinary returns;
- if you want to compute total returns or average returns over multiple periods, use log returns.
Furthermore, many strategies involve long-short portfolios; e.g., a momentum strategy will buy assets that performed well in the past and short assets that performed poorly.
Recall that, when we short a security:
- you borrow the security;
- you sell the security on the market, so you are credited for that sale;
- you have a liability to return the security and pay the lender a lending fee, as well as the interest and dividends;
- at some , you buy back the security.
So, if you initially have in cash and then short a stock for and buy one for , the result is the following:
| Assets | Liabilities |
|---|---|
| Stocks long | Short stock |
| Cash | Equity |
| Total | Total |
Therefore, the total return on the portfolio will be:
If we denote by the share positions of assets (positive for long, negative for short) and consider the riskless asset to be asset , then we have:
where is the percentage lending fee from to .
Intuition: we apply the usual return formula but also take into account the adjustment for stock lending fees.
Note also that the adjustment may be hard to estimate precisely, so we can take a better approach and subtract an estimate of the average lending fee multiplied by the overall fraction held short of the portfolio, that is:
We could also keep track of the long and short legs separately with the constraint that weights sum to ; in this case, we think of the portfolio as a zero-cost long-short portfolio.
Consider (long portfolio) and (short portfolio); we then calculate:
Then the net return on the zero-cost long-short portfolio is the difference:
Accounting for DividendsRecall that the return of asset with price at time that pays dividend is:
(When using Bloomberg to get data, you can use the DPDF function to make the necessary adjustments.)
Note also that CRSP also provides returns that are adjusted for splits and dividends.
Additional adjustments are required if you are subject to withholding taxes on dividends or interest that are not creditable/refundable.
This can be particularly useful when a portfolio has short positions because:
- on long positions, you receive dividends net of withholding tax;
- on short positions, you have to pay full dividends to the lender.
Suppose that your long positions pay subject to tax , and the short positions have dividends of (so you have to pay ). Without capital gains or losses, the return profile is:
Shortcut: to assess the impact of withholding taxes, simply subtract the dividend yield of long positions and withholding tax from your returns.
Furthermore, cross-border investments can create an additional complexity, since part of the foreign withholding tax can be refunded and part can be credited.
Example: US withholding tax on dividends.
If you are a non-US investor and own US stocks, the IRS generally imposes a 30% withholding tax on dividends paid by US companies.
However, most EU countries and Switzerland have tax treaties with the US: with a valid Form W-8BEN completed through your broker, the withholding tax is typically reduced from 30% to 15%.
For a European investor that wants to invest in US equities through ETFs, there are two alternatives:
- Holding a US ETF directly, with a reduced withholding tax of 15%
- Holding an Irish-domiciled ETF with the same withholding tax paid internally by the ETF.
While the solutions may look identical, the second way is much more tax efficient: there is no additional tax on the investor side, while with the first option, there may be additional tax-filing, estate-tax, or withholding-tax complications depending on the country.
On the other hand, for the Swiss investor, the situation is different, since they can claim the 15% treaty withholding tax through the Swiss tax system and recover some or all of it, which is why a US-domiciled ETF can be more efficient, also because they sometimes come at lower costs and spreads.
We now illustrate the case where the domestic country taxes income but not capital gains (i.e., Switzerland).
Assume that capital gains , dividend income , dividends paid on shorts , and the domestic tax rate . Then we have the following:
| Case | Full crediting | Credit limitation |
|---|---|---|
| Dividend income | 200 | 200 |
| Dividends paid on shorts | -100 | -100 |
| Capital gains | 900 | 900 |
| Pre-tax profit | 1000 | 1000 |
| Foreign withholding tax | -60 | -60 |
| Domestic income taxes | 20 | 0 |
| Profit after tax | 960 | 940 |
Note that domestic income taxes = .
Formally, let be the value of the portfolio before any taxes, the aggregate dividends, the domestic tax rate, and the non-refundable part of the foreign withholding tax. We have the following:
| Withholding tax on long dividends | |
|---|---|
| Domestic dividend income tax | |
| Tax credit | |
| Total tax cost |
Intuition: you pay the higher of the two taxes, because the lower one can usually be credited against the higher one.
In terms of returns, the tax is:
and so the after-tax return is:
Suppose now that the profits (including capital gains) are subject to a domestic tax , that is:
Therefore, the drag on returns from taxation is the sum of:
- the product of the pre-tax return and the domestic tax rate ;
- the product of the dividend yield on long positions and the part of the tax that is not refundable.
We now consider the presence of futures contracts. Since they are unfunded positions (i.e., they do not require paying the full asset value upfront), the change in the futures price is settled in cash at the end of each trading day, so the value of the asset is zero and we cannot really compute a return.
Consider , the portfolio return excluding futures, , the futures price, and , the futures exposure (number of contracts times multiplier).
In this case, the change in the total value of the portfolio is:
Therefore, the return with futures is:
(Note that the formula is similar to the previous one, but always remember that weights do NOT need to sum to 1.)
However, when futures positions are rolled (i.e., closing the current position before expiry and opening a new one with later expiry), we make sure to use a given futures contract and not mix contracts with different maturities.
Consider, for example, E-Mini S&P 500 Futures around the September 2026 expiry:
- On September 17, we would use the September contract to compute returns.
- Starting from September 18, we would use the December contract.
One way to do this easily is to configure your code to determine which contract to use. With the generic futures in Bloomberg, the contract is rolled automatically and, using the function GDUT, prices are adjusted automatically for rollover (needed because futures prices differ across maturities and the price spread between maturities reflects the difference between the risk-free rate and the dividend yield).
Formally, for an equity future, the no-arbitrage price is:
where is the stock's current price, is the continuously compounded risk-free rate, and is the dividend yield. The price difference between two maturities and is then:
However, note that futures returns will generally differ from the returns on price and total-return indices. In general, in the absence of market frictions, futures returns equal index returns (including dividends) minus the risk-free rate:
We now give a quick proof of this:
Suppose initially that the value of the underlying price index follows:
where is the dividend yield, is Brownian motion, is the drift, and is the volatility.
We also denote by the risk-free rate, so the price of futures maturing at is:
Using Itô's formula, we get:
Performance measurement
The idea of performance measurement is to relate the portfolio's realized return to risk. Note that performance measures are usually based on excess returns, i.e., the return of the portfolio minus the return of the risk-free asset.
The Sharpe ratio gives the average return of the portfolio in excess of the risk-free rate per unit of total portfolio risk .
It is an appropriate measure for an investor focused on the full risk of the portfolio. However, note that the Sharpe ratio:
- does not distinguish whether returns are generated by systematic or idiosyncratic risk;
- only considers the first two moments of the return distribution.
Another very common performance measure is alpha, which represents the excess return on the portfolio over the return that would have been achieved by investing in a benchmark portfolio with the same systematic risk.
It can be estimated, together with its significance, by regressing the portfolio excess return on the excess returns of the systematic risk factors , i.e. by finding , , and such that:
Note that alpha can be computed using one or more benchmark models. For example, we can consider the market model:
Similarly, we can extend this regression to the Fama–French three-factor model (market factor, SMB size factor, and HML value factor):
By adding the momentum factor, we obtain the Fama–French–Carhart four-factor model:
Lastly, the Fung–Hsieh model, mostly used to evaluate hedge funds and CTAs (commodity trading advisors), takes into account that active strategies may produce nonlinear payoff profiles through the use of leverage, short selling, and derivatives. The model uses seven factors, divided into equity factors (market and size-spread factors), bond factors (bond-market and credit-spread factors), and trend-following factors (bond, currency, and commodity trends). An additional emerging-market factor can eventually be added.
More on this regression can be found here in the famous paper "The Risk in Hedge Fund Strategies: Theory and Evidence from Trend Followers" by William Fung and David Hsieh.
Furthermore, we can define the information ratio (appraisal ratio), which gives the average return achieved by a portfolio in excess of a benchmark divided by the tracking error (i.e. the standard deviation of the return differential). In a formula, we write:
Note that in this case the benchmark can be specified exogenously or estimated using a regression. In that case, the information ratio can be computed from the regression results using and (the regression residual), where the residual standard deviation represents the tracking error:
Measuring timing ability
We usually say that "time in the market beats timing the market..."; however, we now discuss and measure the timing ability of a portfolio. We can do this in two ways:
- by plotting against the market return;
- by comparing portfolio returns and market returns.
Practically speaking, this analysis is particularly relevant when considering a portfolio that rotates between stocks and bonds (the same analysis can be extended to other asset classes by using the market return as the return on the asset class and as the exposure to the asset class).
We can first state that if a strategy is successful at timing the market, there should be a positive correlation between the portfolio's and the market return (or between and the difference between the market return and the bond return, i.e. the excess return to bonds).
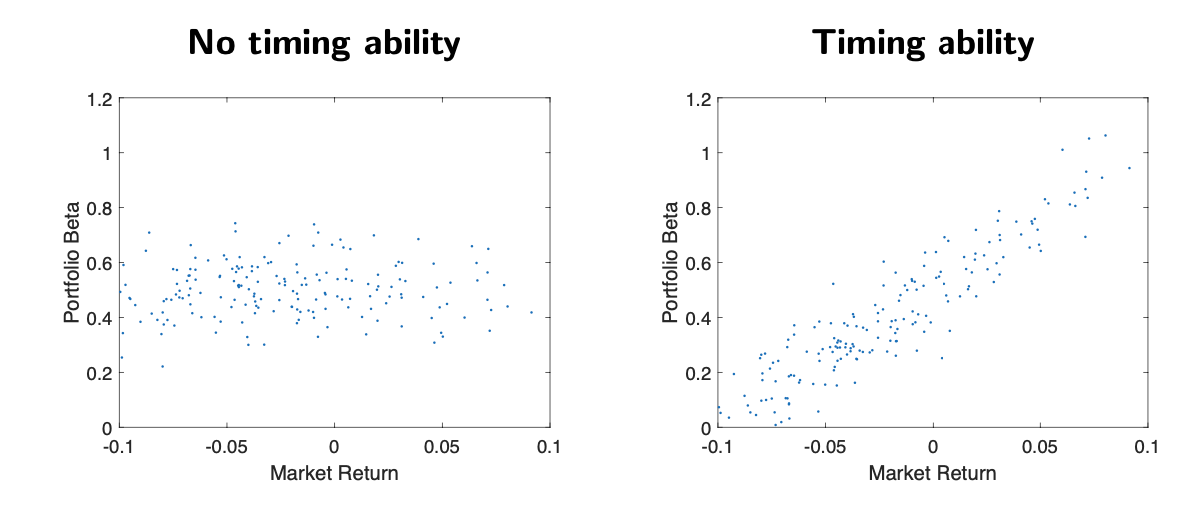
Secondly, if a strategy is successful at timing the market, the portfolio's exposure to fluctuations in the market is greater when the market goes up and smaller when it goes down, yielding a convex relationship between market returns and portfolio returns (intuition: a portfolio should seek to invest when assets go up and stay liquid when they go down).
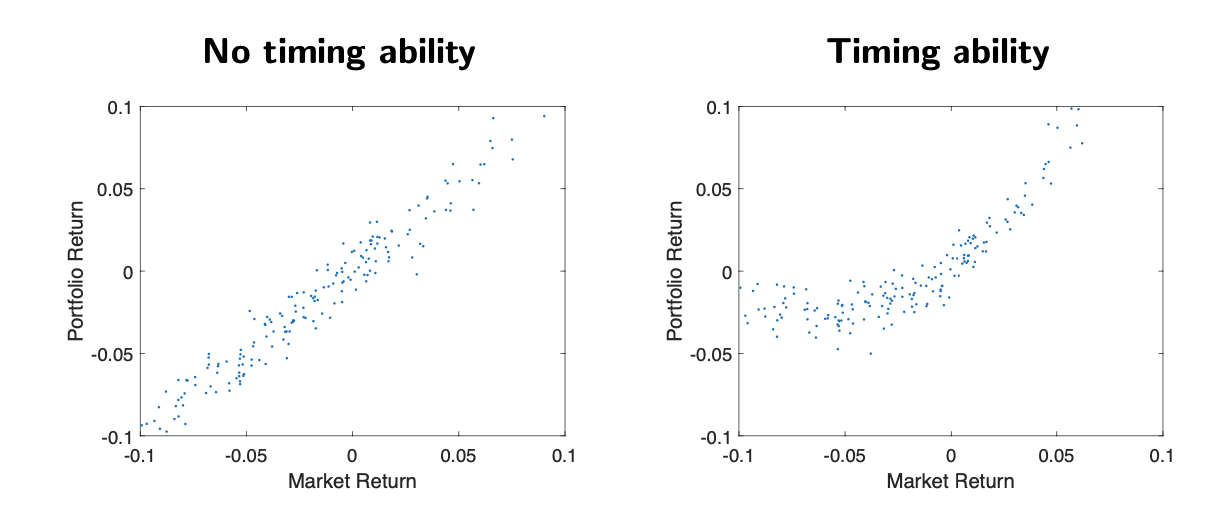
Therefore, we can detect timing ability by testing for nonlinearity in the relationship between market returns and portfolio returns. One common approach is the Treynor–Mazuy procedure, which fits a quadratic curve to the returns using the following (linear, despite the quadratic curve!) regression:
In the case of good timing ability, we expect a positive and statistically significant coefficient.
Furthermore, the Merton–Henriksson procedure tests whether the portfolio return resembles the payoff diagram of a long market position plus a long call on the market by running the regression:
Again, in the case of positive timing evidence, we expect a positive . Unfortunately, the explanatory power of these tests is still low.
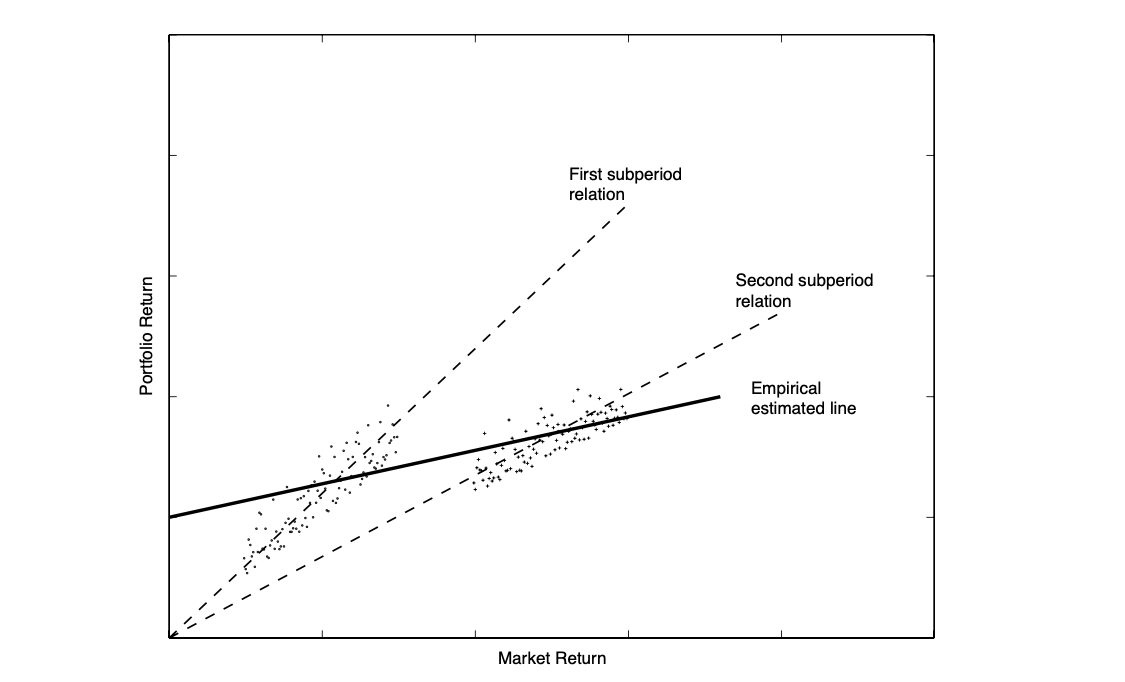
One last point: note that and will be distorted if the strategy involves timing but timing is not modeled explicitly when trying to measure performance, i.e. if the analysis assumes constant exposure.
For example, suppose a strategy:
- holds mostly equities during bull markets;
- moves to cash in the opposite case.
The returns may look strong, and the regression may attribute these returns to (skill) and (sensitivity to the market). However, part of the performance may simply derive from when the strategy is invested, rather than from stock selection itself, creating a timing bias (in the sense of model misspecification). A more accurate analysis would model time-varying exposure (i.e. ) using:
Principles of Strategy Development: Statistical Significance, Overfitting, Biases and Transaction Costs
When developing a strategy, it is essential to keep the following in mind:
- always worry about statistical significance
- be aware of overfitting and data mining ("if you stress numbers enough, they can tell you anything")
- be aware of biases! (backfilling bias, selection bias, look-ahead bias, etc., etc.)
- account for transaction costs!
Generally speaking, unless a relation/effect is statistically significant, it should not be used as a starting point for an investment strategy.
Firstly, consider that many asset returns are not normally distributed (e.g. stock returns in the short period have fat tails, options have large skewness...), and a consequence of this is non-normality of the residuals in return regressions.
Secondly, consider that volatility is time-varying, so asset returns are not independent and identically distributed.
Therefore, when running a regression, we have that:
- by the Gauss-Markov theorem, the OLS estimator is BLUE (Best Linear Unbiased Estimator; I've written more about it here in my econometrics notes!) if the errors are independent and identically distributed (IID), so note that normality is not required!
- When the residuals are not IID (i.e. if they are correlated or there is heteroskedasticity, so error variance changes with ):
- the OLS is still unbiased but it is inefficient, and GLS (Generalized Least Squares) is BLUE.
- the OLS standard errors are incorrect, and we should instead use robust standard errors.
We start by supposing we are looking for a strategy with a high Sharpe ratio. We can then say that the larger the number of trials made when developing the strategy, the longer the length of the backtest required for the expected out-of-sample Sharpe ratio to be positive.
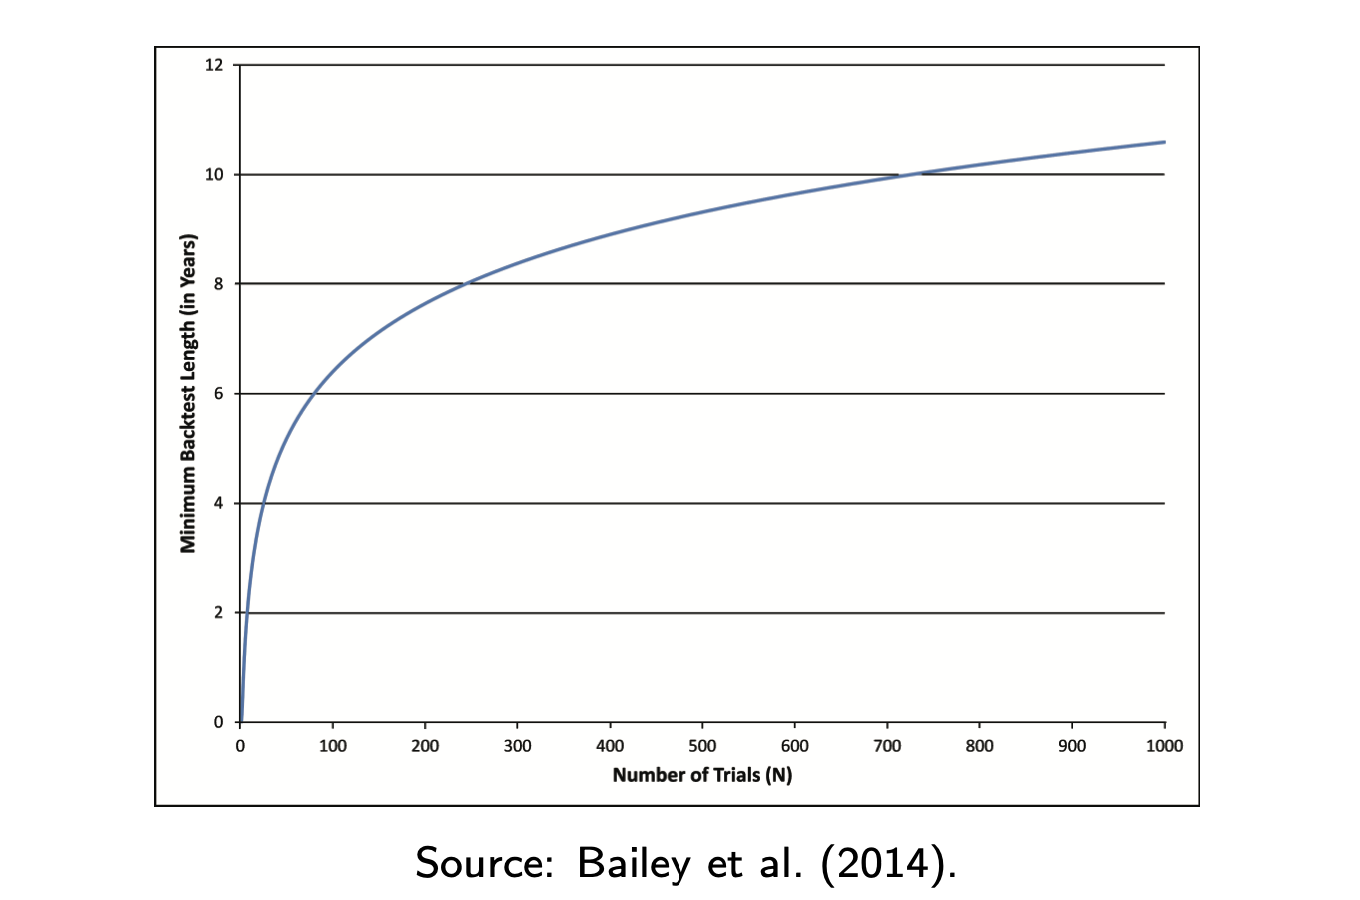
Therefore, we list some approaches that can be used to avoid overfitting:
- keep track of the number of trials and keep this number low!
- keep the strategy relatively simple
- run out-of-sample tests by splitting data into training/testing datasets
- investigate the robustness of the strategy to changes in parameters
Furthermore, beyond overfitting, particular focus should be placed on biases since they can arise in several places and times, in the way assets/data are collected, considered, and analyzed.
In particular, we define look-ahead bias as the tendency to use information that was not actually available at the time the investment decision had to be made. Note that this bias is particularly evident in backtesting and signal detection.
For example, suppose that we are trying to predict returns using a regression .
To avoid look-ahead biases, we have to make sure that was really known at time (i.e. that is -adapted... but this is another story: if you want to know a bit more about stochastic equations and filtrations, well, prepare to suck... maybe my notes here can be a starting point!).
Note that this problem is particularly relevant in finance since accounting/earnings data are often published with a delay, some financial market data (interest, mutual fund NAV) are published with a lag of one trading day, there are always different time zones in place and, finally, data are often revised after publication!
On the other hand, selection bias arises when the sample is not randomly drawn from the underlying population, causing assets with particular features to be over-/under-represented in the sample. The most reliable fix in this case is always the simplest, yet most difficult to implement in practice: include the full population!
Survivorship bias, in particular, is a form of selection bias that arises when the sample used in the analysis only includes assets that are still traded at the end of the sample period. For example, evaluating mutual fund performance using only funds that still exist excludes all the funds that either closed or merged, so the surviving sample appears to have stronger historical performance than the full initial sample. On the other hand, almost off-topic in finance, studying only successful startups and concluding that founders who drop out are still very successful... well, this is obvious... you don't see dropout students that are both without money and a degree.
In general, survivorship bias can be avoided by using the population of all assets in a given category, regardless of their current status, (but this could be very hard to do, especially when looking for public data) or by using the constituents of an index from a period previous to each investment decision as the starting point/sample.
Backfilling / instant history bias arises instead when historical data are backfilled into a database when an asset is added to it. For example, this happens when a hedge fund database adds a fund and includes returns before the inclusion date (it can be fixed by dropping data for assets before their inclusion date).
Transaction costsAssessing the impact of transaction costs requires a priori estimates of costs and, more difficult, estimates of the strategy's turnover. The case of proportional transaction costs is easiest to deal with.
If we denote by the trading cost per currency unit (including commissions, bid-ask spreads, and any other transaction taxes or costs), a quick estimate of the effect of transaction costs on the return per period is just the product of and the strategy's average turnover (assuming all assets have the same cost, but this can be viewed differently simply by taking individual costs and turnovers).
If we want more granularity, we can subtract the product of costs and turnovers at the end of each period. To do that, consider as the vector of portfolio weights and as its component-wise absolute value. In this case, the total turnover in period can be approximated as:
but note that this approximation does not account for the change in portfolio weights induced by differences in returns across assets. To include this, we can compute the portfolio's weights at the end of the period and calculate the turnover:
Constant-Allocation, Timing and Selection Strategies: Risk Premium Estimation and Predictive Models
Risk Premium EstimationWe start by saying that the simplest strategies are the ones targeting a constant allocation to a number of asset classes, so the key decisions are:
- which asset classes should we consider?
- how often should the portfolio be rebalanced toward target weights?
Indeed, note that for those strategies, the return depends on the risk premia of the asset classes over time, and the size of the allocation depends on the (unconditional) risk premium per unit of risk, the level of risk, and the timing of the losses of each asset class.
Unconditional risk premia on different asset classes can be estimated as the difference between the average return on the risky asset and the average return on the riskless asset. For example, we can say that:
- equity risk premium: average total return on stocks
- bond risk premium: average total return on long-term debt
- credit risk premium: average total return on risky debt
- real estate risk premium: average total return on real estate
- commodity risk premium: average total return on commodities ... and so on...
Deep dive: if you want to know more about risk premia, well, it is better to spend some time on Aswath Damodaran's personal/official page, where he writes about asset pricing and personal finance and, on a periodic basis, publishes estimates of equity risk premia around the world. Enjoy!
However, notice that average return estimates are noisy, so we must rely on long sample periods. Furthermore, note that risk premia are not constant over time and therefore estimating conditional risk premia is much harder than obtaining unconditional estimates. (Recall that the unconditional risk premium is the long-run average return without conditioning on/knowing the current market information, while the conditional risk premium is the expected excess return given the information available today, such as valuation, interest rates, volatility, and market conditions.)
In this context, the Fama–MacBeth method is a common approach to estimate risk premia. Suppose we have assets with excess return on asset given by:
where denotes the factors driving the returns and is an asset-specific constant (note that we write and not so as not to confuse it with alpha!).
Given this, the method relies on the following steps:
- run time-series regressions, one for each asset , and obtain all the values (i.e. we estimate its factor exposures : how much an asset moves with each risk factor);
- for each time period, run a cross-sectional regression of excess returns on the values to estimate the returns on the factors during a period, i.e. (note that we regress on values; and are our coefficient estimates):
- we then obtain estimates of (the asset-specific residual) and the values (the factor risk premia). We can then consider their time-series average from all the cross-sectional regressions:
Furthermore, to test the significance of risk premia and asset-specific residuals, we can compute the covariance matrices as:
Note that the resulting standard errors are not perfect, since they do not account for the fact that the s are estimates, not real data. We could account for this by running a single cross-sectional regression for the sample average excess return and using formulas for the standard errors, in this case by running:
Timing Models
The goal of timing models is to find indicators for which the conditional return distribution differs from the unconditional return distribution, relying on the predictability of assets.
As a consequence, this goal translates into identifying a set of variables that forecast the future return distribution in order to identify periods in which risky-asset returns are more attractive.
Consider now , the predictive variable being considered, and , the future excess return with a forecasting period of . To test if has predictive power, we can split the sample based on the value of and compute summary statistics for for the subsamples, then run a test for identical distributions by estimating the predictive regression:
where the first tells us about returns, the second about variance.
Furthermore, we regress using dummy variables instead of :
Note that if the critical values and the regression coefficients are estimated with rolling or expanding windows, then you are working out-of-sample. Of course, the forecast should be based on information available within the window used for the estimation to avoid look-ahead bias.
Common predictors are:
-
valuation ratios
- dividend/price ratio
- earnings/price ratio
- book-to-market ratio
- consumption/wealth ratio
- interest-rate variables: (reflecting monetary policy and market expectations about the business cycle)
- T-bill rate and the T-bill rate minus its 12-month average
- term spread (TS) (long-term yield minus short-term interest rate; it reflects business-cycle movements and anticipates changes in monetary policy)
- credit spread (CS) (BBB bond yields minus AAA yields; represents the market assessment of future default risk)
-
volatility variables
- realized volatility
- implied volatility (example: VIX, which represents perceived risk)
-
macro variables
- GDP
- inflation
- news sentiment
Selection models try to generate returns by selecting assets from a cross-section based on some criteria, usually from the same asset class. Some examples are below:
- carry: select currencies based on their interest rate
- value: select stocks based on their book-to-market ratio
- momentum: select stocks based on their past return
Usually, we proceed as follows:
- sort the assets into groups based on the value of the variable of interest. The number of groups is chosen to find a balance between stronger effects at the extremes and reduced idiosyncratic risk (which requires many assets per group).
- build portfolios of the assets in the groups
- investigate return properties of the portfolios
However, note that in many cases we want to incorporate several variables; in this case, bivariate (or three-way) sorts can be valid approaches for sorting over selected variables in either of two ways:
- with an independent sort, where we sort on different variables independently, so the resulting portfolio will be the intersection of portfolios built on individual variables, and the number of assets in each portfolio will strongly differ if the two variables are related;
- dependent sort, where we first sort on a first variable and then, within each quantile of the first variable, sort based on a second variable. In this case, the number of assets in each group is similar, but the results depend on the order chosen.
Furthermore, we can use the scoring method by attributing scores to each asset for each variable considered and then grouping them by the overall score.
- For each considered variable, we attribute a score to each asset based on its quantile, making sure that higher means better for all.
- compute an overall score by summing, averaging, or weighting (be aware of overfitting!)
The last approach involves regression to estimate the expected returns.
- we use the Fama–MacBeth method or cross-sectional regression to estimate the exposure of the assets to the factors and their risk premia to estimate and , as done before
- we compute the expected excess return on each asset based on the factor exposure
Once we have selected a selection method, the resulting portfolio can be implemented in three ways:
- long-only portfolios
- long-short portfolio, so the return for the period is equal to:
- the return of the long portfolio
- the risk-free rate
- the cost of the portfolio held short
- the lending fees of the portfolio
- long portfolio with a hedge for market risk, where the hedge is implemented using futures, so the return of each period is given by:
- the return of the long portfolio
- the hedge ratio times the percentage price change of futures
Combining Strategies and Implementation: Portfolio Weights, Leverage, Short Selling and Levered ETFs
Combining strategiesIndividual strategies do not work all the time, so it can be useful to manage assets using multiple strategies. In this case, instead of running portfolio optimization to allocate funds, it is often more useful to have heuristics since they are usually more robust.
When combining strategies, alpha and the factor exposure for the overall portfolio are the weighted averages of the underlying strategies. However, for the Sharpe ratio, we cannot say the same.
Suppose for example we want to run a mean-variance portfolio optimization; let be the vector of expected returns and the covariance matrix. Then the tangency portfolio is:
with and .
In this case, the Sharpe ratio will be:
However, suppose now that we do NOT trust the estimates of expected returns. Then the candidate portfolio would be the risky-asset-only global minimum variance, defined by:
We also introduce the risk parity portfolio, with weights according to the inverse of their volatility, so we have:
If we let be the pairwise correlation between and , expected returns and variance are:
which results in the Sharpe ratio:
Lastly, for the equally weighted portfolio, , and we have the following:
where .
From these four expressions, we can compute the portfolios and the Sharpe ratio from different approaches:
- if the Sharpe ratios do NOT differ, it is advisable to go for an equally weighted portfolio;
- if they do, tilting the portfolio toward weights recommended by other approaches can be justified;
- empirically, risk-parity portfolios tend to be more robust
- if the tangency portfolio recommends shorting a strategy, we should drop it (this typically happens if it is highly correlated with another one but has a lower expected return per unit of risk).
(Note that we could also look at skewness and worst return, as the Sharpe ratio does not cover everything.)
Implementation Issues
Some common aspects to consider for implementation:
- are the instruments accessible?
- is there any minimum number of transactions required, what are the trading hours, in which currencies do assets trade, and are they OTC?
- are the positions subject to counterparty risk?
- commissions, spreads, taxes
- are instruments always available or substitutable?
- when should we buy? at open, close, or during the market session?
In general, with strategies with lower turnover, the exact time of the transaction should not be critical. On the other hand, for high-turnover strategies, it is important to know when you trade, especially because many exchanges have special rules for trading at the open/close time, and prices at these times are usually more volatile.
Leverage Constraints and Problems with Short PositionsIf the strategy uses leverage, it is important to make sure that the strategy can obtain it and account for its cost (there's no free lunch!)
The amount of leverage is usually driven by regulation, standards, and the broker, but usually we have:
- for stock/bond positions, you usually get up to 2:1 total
- for futures positions, it depends on the margin requirements and is usually larger
- for long option positions, it is generally hard to get leverage on top
- for short option positions, margin requirements may exceed the contract's value (especially for OTM options)
- for OTC derivatives, each bank/broker has its own rules
Particular issues arise if the strategy uses short positions in securities, since in order to short a security and hold it overnight, we need to borrow it:
- usually, banks/brokers have inventory that they lend for a fee, which is larger if many people want to short at the same time;
- whenever you borrow a security, the lender can request it to be returned. In this case, the bank/broker has to borrow it from someone else, but if they cannot, they can also recall your security, and this will force you to close the position;
- additional risk arises when regulators impose short-selling bans when a security drops sharply in value over a short period. In this case, existing short positions are usually grandfathered, but you cannot open new ones.
Because of these problems, when we analyze a long-short strategy, we may:
- investigate the profitability of the short and long legs separately;
- consider alternatives to shorting.
Conceptually, the short leg of a strategy can improve performance in two ways:
- selection of securities that we expect to drop in value;
- reduction of market risk.
In particular, a well-functioning approach works as follows:
- we compute the performance statistics of:
- the full long-short strategy;
- a strategy involving only the long leg;
- a strategy involving only the short leg;
- a strategy involving the long leg and shorting the index futures.
- if the long-only strategy has the best performance, we ignore shorting;
- if the strategy with index futures is close in performance to the full long-only strategy, we use the strategy with futures;
- if the strategy using index futures is significantly worse than the full long-only strategy, the full long-only strategy is then preferred, as long as it has a realistic implementation:
- in this case, you may try to get a sense of whether you could encounter problems borrowing;
- if this could be a problem, we can synthesize shorting in different ways:
- by using options (long put, short call), but be aware of liquidity and transaction costs;
- by selling futures and buying all the index members that we do not want to short;
- by shorting ETFs or buying short ETFs in which the stocks we want to short have a large weight.
If you want to know a bit more about leveraged ETFs and focus on some technicalities... well, I have written something here on my blog.
We now go back to the graph showing the returns on three ETFs around the 2007-2008 financial crisis:
- IYF (1X long the Dow Jones U.S. Financial Sector Index)
- UYG (Ultra Financials, 2X long)
- SKF (Ultrashort Financials, 2X short)
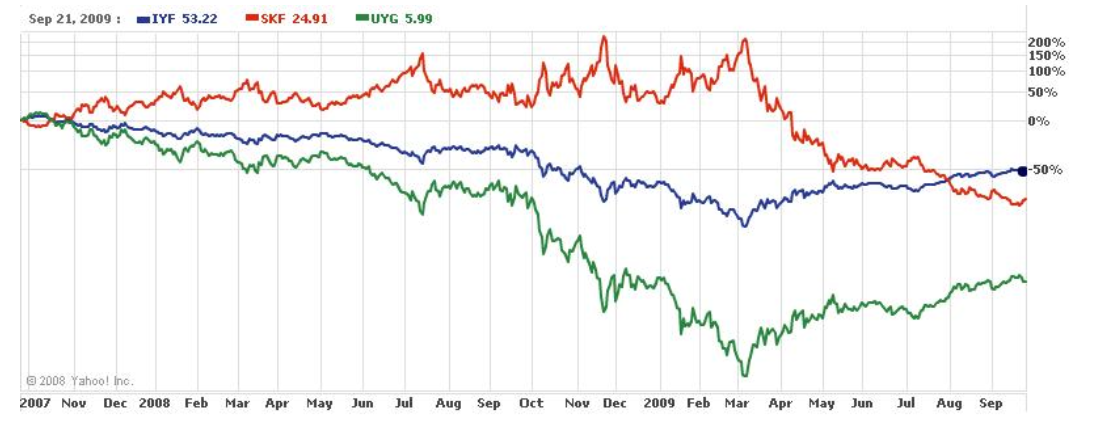
We immediately notice that over the 2-year period considered, IYF resulted in a 50% loss, and SKF didn't reach 100% again, so it was still showing a loss. As we can see then, both the leveraged long and the levered short ETFs were worth less than the underlying at the end of the period. The root cause is that the ETFs are rebalanced dynamically on a daily basis, so, at the end of the day, when the underlying index price went up,
- the levered ETF has to increase its position to keep the leverage ratio constant;
- the short ETF reduces its short position.
So, levered and inverse ETFs tend to do well in trending markets and do poorly in markets with reversals.
Assume, for example, a 2x-levered ETF (rebalanced daily) investing in an index, and assume that the ETFs and the underlying index are both worth 100 at . Then assume that at the index goes up by 10%, and then, at , it either rises another 10% or reverts to 100.
| Period | ||||
|---|---|---|---|---|
| Continuation | Reversal | |||
| Index | 100 | 110 | 121 | 100 |
| ETF Index Position | 200 | 220 | 264 | 218.2 |
| ETF Value | 100 | 120 | 144 | 98.2 |
| Required ETF Index Position | 200 | 240 | 288 | 196.4 |
| Required ETF Trade | — | Buy 20 | Buy 24 | Sell 21.8 |
| Required ETF Borrowing | 100 | 120 | 144 | 98.2 |
More generally, the table summarizes the expected gross return from a 1-year investment in each ETF, depending on daily return autocorrelation .
| Autocorrelation | Long ETFs | Short ETFs | ||||
|---|---|---|---|---|---|---|
| 1X | 2X | 3X | 1X | 2X | 3X | |
| 1.0423 | 1.0692 | 1.0797 | 0.9443 | 0.8777 | 0.8029 | |
| 1.0510 | 1.1045 | 1.1607 | 0.9515 | 0.9053 | 0.8615 | |
| 1.0647 | 1.1637 | 1.3055 | 0.9643 | 0.9547 | 0.9703 |
In general, leveraged ETFs perform poorly when volatility is high because of volatility drag. We can approximate the annualized continuously compounded return of a leveraged ETF with leverage
where is the underlying asset's average return and is the variance of its returns. Therefore, the approximate annualized simple return is:
For small returns:
Taking averages gives:
The second term is the volatility drag. It is negative and increases with the square of the leverage.
Hence, a levered or short ETF requires adjusting the size of the ETF positions used to undo the effect of the dynamic rebalancing inside the ETF (but of course you don't need to rebalance if you backtest the strategy already while using a levered/short ETF.)
Equity Risk Premium and Return Predictability: Valuation Ratios, Dividend Yield and the Term Premium
The equity risk premium (ERP) is the excess return of the equity market over that of a low-risk asset. It is usually measured against Treasury bill or Treasury bond returns.
We can then distinguish between:
- historical ERP: the extra return earned in the past
- expected ERP: the average extra return from investing in equities rather than in T-Bills over the next h months, quarters, or years:
Note that if you borrow capital and invest it in the equity market, you earn ERP.
Note also that we can write the optimal portfolio formula for a mean-variance investor with risk aversion as:
The economic idea is that the ex ante ERP is the compensation required by investors to allocate capital to risky assets rather than to the risk-free asset, and the equilibrium reasoning predicts a positive ex-ante ERP because stocks do poorly in bad times.
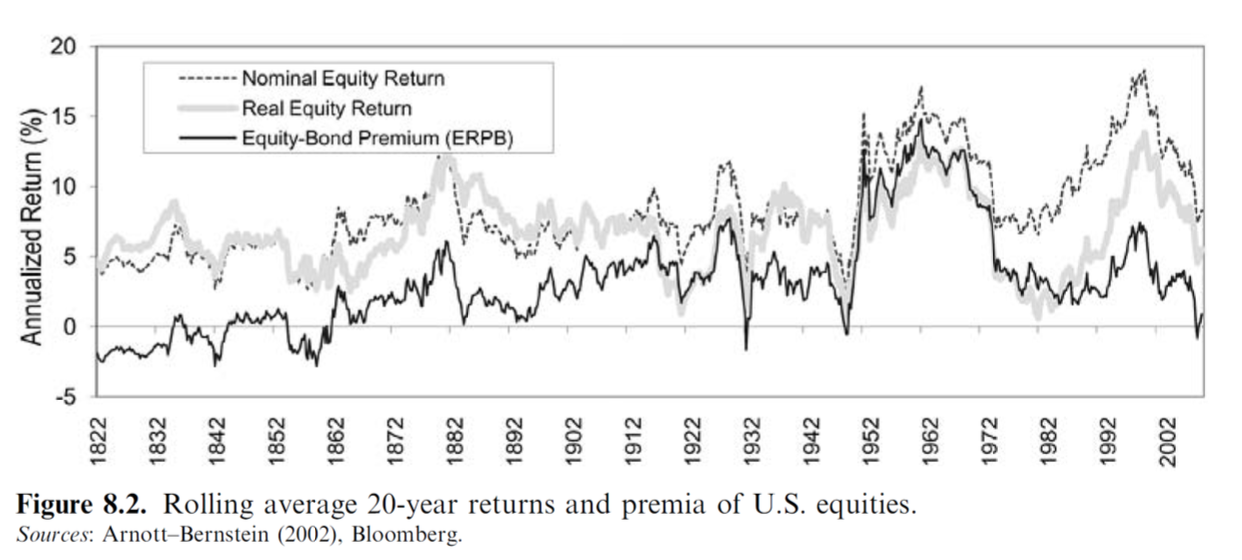
To estimate the historical ERP, we can compare historical average returns of the stock market with those of the risk-free asset by adopting a long sample period, since stock returns are volatile (note that we can distinguish between nominal and real returns).
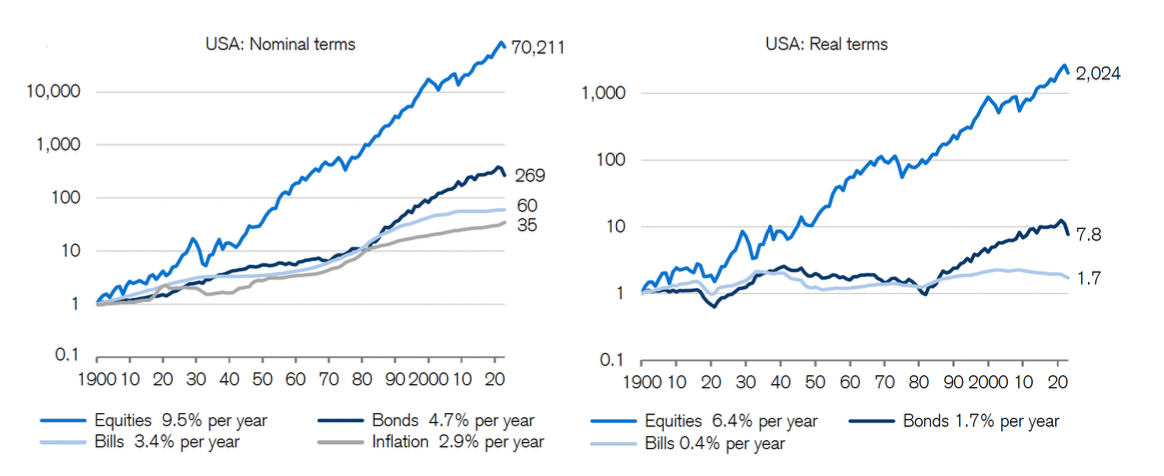
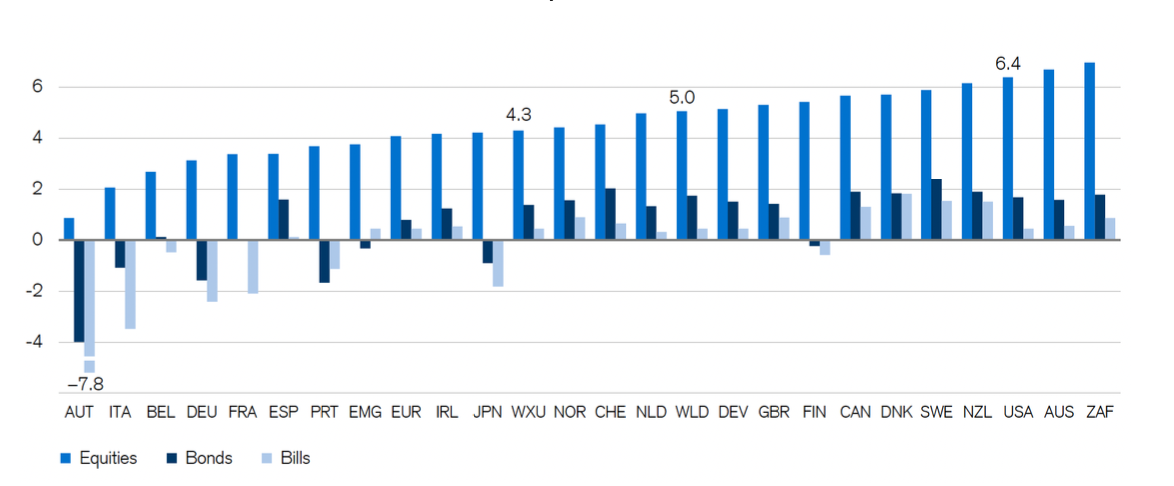
Even if the ERP is positive for all countries, it can vary a lot over time:
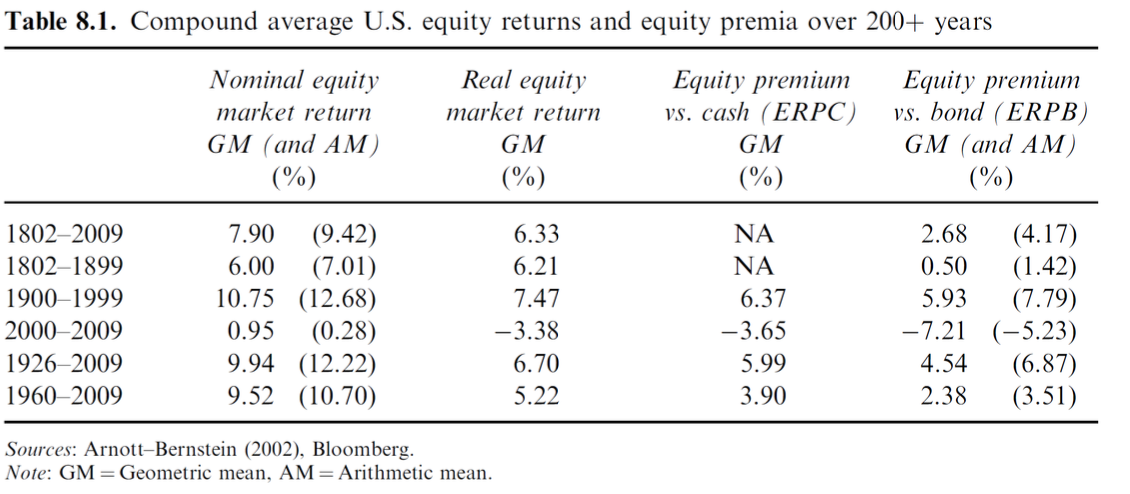
On the other hand, estimating the expected ERP is much more difficult. We cannot simply use the historical one because there is a negative relation between changes in future and historical ERPs (if investors require the future ERP to decrease, realized equity returns are positive, and so the historical ERP increases).
To understand this relation, we can decompose stock returns with price and dividend as follows:
where the first term includes the dividend yield, the second the dividend growth, and the last one the multiple expansion, which drives the changes in the expected ERP over the short term while, in the long run, it accounts for a smaller part of the ERP.

We can then use this decomposition to get an estimate of the ERP by assessing each component of and subtracting the real risk-free rate (for the risk-free rate, we can consider the return of short-term T-bills in the US).
Equity Return Predictability
We first recall that timing models are based on predictability, which studies patterns in the return distribution over time to identify sets of variables that forecast the future return distribution. We previously saw that predictability is about finding indicators for which an asset's conditional return distribution differs from its unconditional distribution.
We also saw that, in order to assess whether a variable has predictive ability, we have to:
- split the sample based on the value of , compute statistics of for the subsamples, and run a test for identical distributions
- estimate the predictive regressions:
We then assess the significance of the betas (the first tells us about expected returns; the second, about variance).
- run a predictive regression using dummy variables instead of :
Price/Dividend Ratio Predictor
We've seen that dividend yield is a key component of long-term equity returns; its inverse is the price/dividend ratio. However, we can notice that the P/D ratio varies strongly over time.
To understand how we can estimate the ERP from the price/dividend ratio, consider a firm that pays a dividend and is expected to pay a terminal dividend .
Consider , the current price. Then the gross return on an investment in the firm is:
If we solve for , we get:
Therefore, the P/D ratio moves due to changes in expected dividend growth or changes in expected returns.
There are two views on the information contained in the P/D ratio:
- traditional view: expected returns are more or less constant, and the P/D ratio is driven by changes in expected dividend growth. Therefore, a high P/D ratio should predict high future dividend growth. For a forecasting horizon , this can be tested with:
This view was challenged by Shiller (1981) in the paper Do Stock Prices Move Too Much to be Justified by Subsequent Changes in Dividends? (American Economic Review), which shows that prices move far too much to be explained by subsequent changes in dividends alone.
- modern view: the P/D ratio is driven by changes in expected returns. Therefore, a high P/D ratio should predict low future returns. This can be tested with:
Fama and French (1988) ran this regression in the paper Dividend Yields and Expected Stock Returns (Journal of Financial Economics), finding that the dividend yield predicts returns, especially at long horizons. Cochrane (2008), in The Dog That Did Not Bark: A Defense of Return Predictability (Review of Financial Studies), adds that dividend growth is not predictable, so the P/D ratio must move because of expected returns. Goyal and Welch (2008) are more skeptical in A Comprehensive Look at the Empirical Performance of Equity Premium Prediction (Review of Financial Studies), showing that this predictability is weak out of sample. For an overview of the discount-rate view see Cochrane (2011), Presidential Address: Discount Rates (Journal of Finance).
We can analyze this view further by rewriting the return definition and taking logs, as Campbell and Shiller (1988) do in the paper The Dividend-Price Ratio and Expectations of Future Dividends and Discount Factors (Review of Financial Studies).
If we take expectations, we obtain:
- If the expected returns are constant at , then this becomes:
If expectations are rational (unbiased), then we have , with , so we obtain:
- If the expected dividend growth is constant at , then we have:
Under rational expectations, , with , so we have:
For example, between 1927 and 2005, the D/P indicator predicted future returns rather than dividend growth.
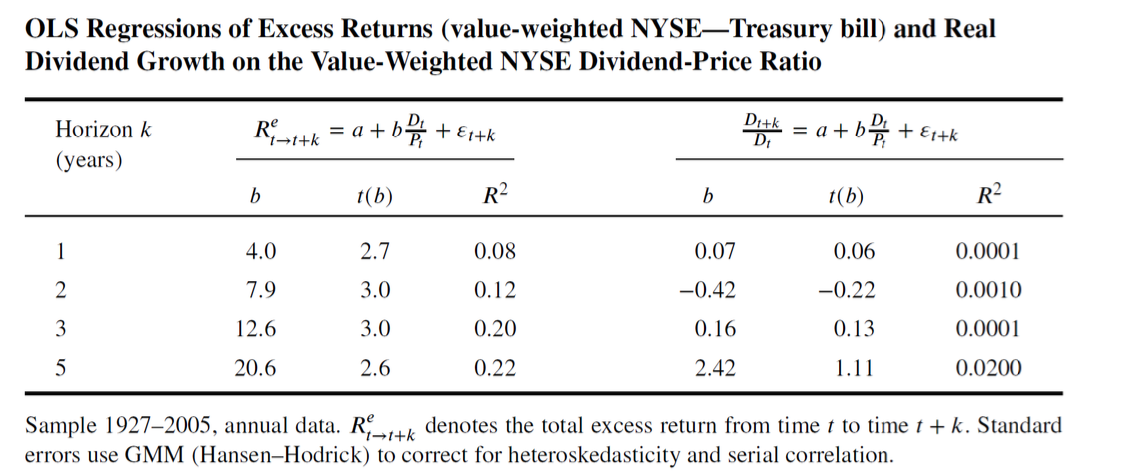
However, the out-of-sample predictive power is still poor, making it difficult to use the ratio to improve portfolio performance.
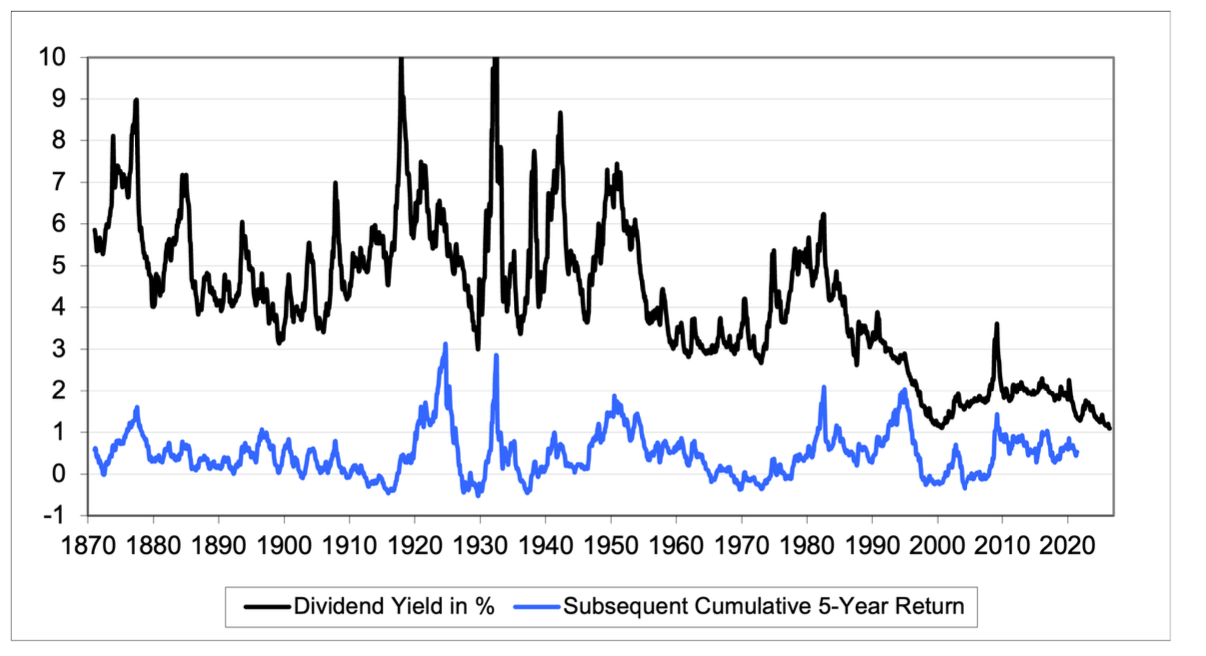
Note that the one-period model can be extended to multiple periods, as Campbell and Shiller did in 1988. In this case, we start from the one-period return.
If we substitute forward one period, , we have:
If we iterate forward by imposing a limiting condition that P/D does not explode faster than returns, we can take expectations and write:
Intuition: today's P/D ratio is high if people expect high future dividend growth or low future return.
Note that, due to its complexity, we often use the approximation suggested by, again, Campbell and Shiller using logs, and we obtain:
that, if we do a Taylor approximation around the log at a point , i.e.
where and .
We get:
where and is always less than, but close to, one.
If we iterate forward and impose the limiting condition, we take expectations:
However, in his famous paper Do stock prices move too much to be justified by subsequent changes in dividends?, Shiller immediately noticed that, since equity prices are quite volatile, this variation in price was not justified by changes in dividends or cash flow. It turns out that excess volatility is the same as return predictability, i.e. if prices are "too high", subsequent returns will be low as prices move back to their "correct" level (mean reversion).
So from the multi-period price-dividend equation, we can compute the variance of the P/D ratio as:
We can then see that the dividend yield can only vary if it forecasts changes in future dividend growth or returns. This implies that P/D empirically predicts returns rather than dividend growth, and that variation in the P/D ratio comes from movements in expected returns.
Note that this analysis was conducted at the aggregate level (focusing on the index). Vuolteenaho in 2002, in the paper "What Drives Firm-Level Stock Returns?" (Journal of Finance), showed that most of the variation in single-stock returns comes from cash-flow news rather than expected return news.
Indeed, at the single-stock level, D/P is driven by changes in cash flows, while at the aggregate level it is driven by changes in expected returns.
This happens because cash flow news about single stocks is highly idiosyncratic and is removed by diversification when stocks are combined into portfolios; movements in the aggregate portfolio/index mostly reflect changes in expected returns, which are driven by macro conditions.
Other Profitability Ratios
Beyond the traditional and well-known dividend-price ratio, we can now consider, for example, the earnings/price ratio (E/P) and the cyclically adjusted P/E ratio (the ratio of the 10-year moving average to price, denoted by E10/P, CAPE, or the Shiller ratio), which have some predictive ability.
However, note that the CAPE ratio is usually more stable than the E/P ratio since it is less affected by single-year events. Furthermore, E10/P is pretty good at catching periods of low expected returns and periods of discrepancies between fundamentals and valuations.
(Note that the index is also named the "Shiller ratio" because it was popularized by the famous economist Robert Shiller to evaluate whether a stock is undervalued or overvalued.)
Consider, for example, the following plot and notice the crisis and the corresponding peaks in the CAPE ratio: during the dot-com bubble, it reached 44.4, and, as of some months ago in August 2026, it was again very high.
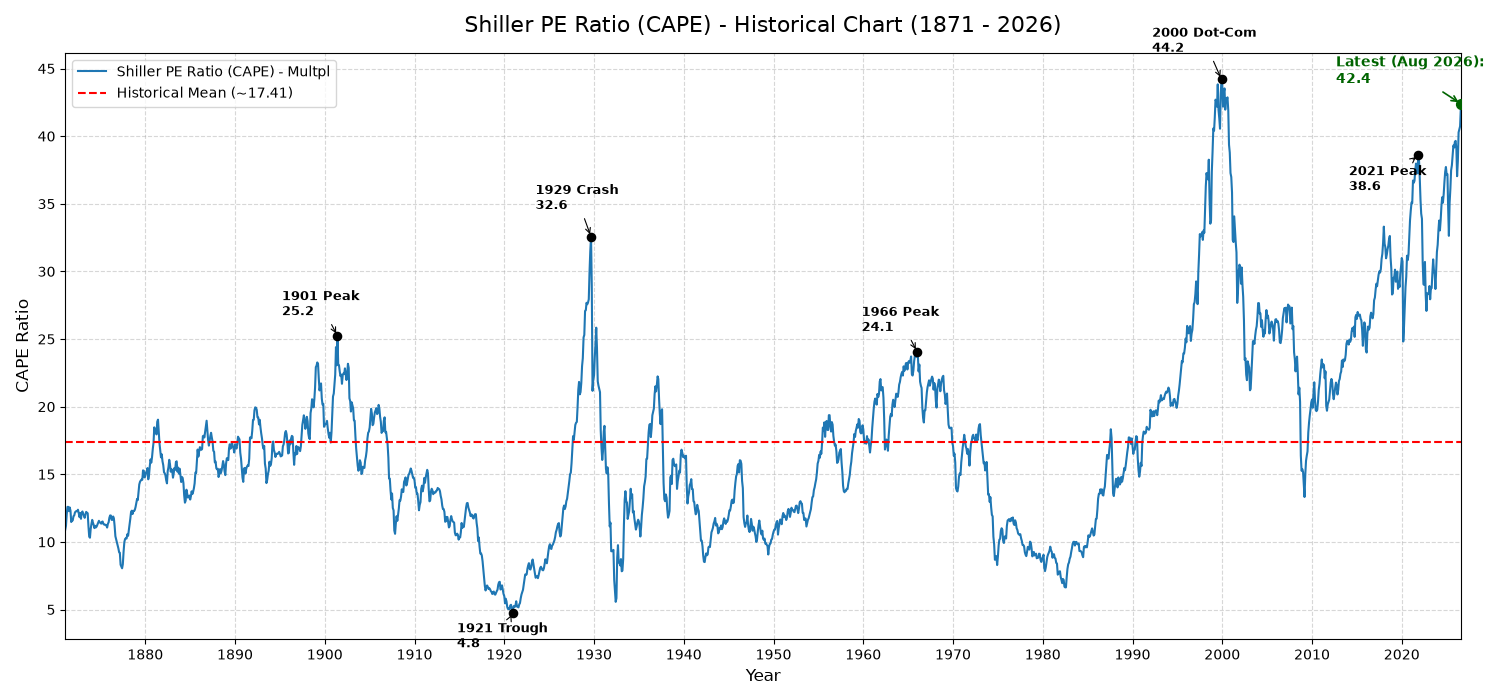
If you want a nice live update on the Shiller ratio, click here!
However, note that there's a lot of criticism around it: firstly, the CAPE ratio might not be so useful because it is backward-looking and does not take into account future trends. Furthermore, it relies on generally accepted accounting principles (GAAP), which have undergone major changes in recent years, so we cannot compare today's CAPE with the same metric from years ago.
D/P and the term premium
Fama and French, in their 1988 paper "Dividend Yields and Expected Stock Returns," predict returns on stocks and long-term corporate bonds using the D/P and the term premium (TP), defined as:
Firstly, they discovered that D/P and TP predict returns in both markets, so this suggests there is a common variation in expected returns across markets.
Furthermore, one year later, in their 1989 paper Business Conditions and Expected Returns on Stocks and Bonds, they found that expected returns on stocks and bonds are linked and share a common counter-cyclical component.
In particular, they ask whether the same variables that track the business cycles also predict returns on stocks and bonds by regressing returns on three predictors, at horizons from one month to four years:
- dividend yield on the market portfolio (high in bad times since prices are low)
- default spread, BAA yield minus the AA yield (widens in recessions and stays wide afterward)
- TS (low near the cycle peak; it moves faster than D/P and tracks shorter cycles)
The main finding is that all the regressors have predictive power for both asset classes, with growing with the horizon. In particular, the pattern is counter-cyclical: expected returns are highest at business cycle lows and lowest at the peaks.
Furthermore, different variables capture different parts of the cycle: D/P and the default spread focus on the long-term persistent component, while the TP focuses on the short-term cycle and relates more to bond returns. Lastly, the variation over time in the risk premium related to D/P is stronger for low-grade bonds than for high-grade bonds and stronger for stocks than for bonds.
Volatility, News Sentiment and Seasonality: Further Predictors of Equity Returns
VolatilityWe recall that the optimal exposure to stocks depends on the risk-return trade-off, not just on the ERP; i.e., we have that:
Moreira and Muir, in their 2017 paper "Volatility-Managed Portfolios," show that return variance is highly forecastable, since it is persistent and tends to cluster. In particular, a highly volatile month is followed by another turbulent month, and autocorrelation is high.
However, they also show that expected returns do not move much with variance: after a high-variance month, the market's expected return does not necessarily change.
The intuition in a mean-variance framework says that investors allocate to the risky assets (stocks), so they should scale exposure to stocks after volatile periods. However, the authors argue that most investors do not do this, as they are usually buy-and-hold investors and target constant exposure, so their risk changes a lot during crises and their Sharpe ratio drops.
On the other hand, a volatility-scaled portfolio with exposure to stocks , where is the average exposure to the strategy (chosen to match the unconditional standard deviation of the buy-and-hold portfolio) and is the realized variance of the previous month, can improve the Sharpe ratio.
News Sentiment
Sentiment analysis uses computer software to understand the tone of news stories and is then used to time exposure to the equity market.
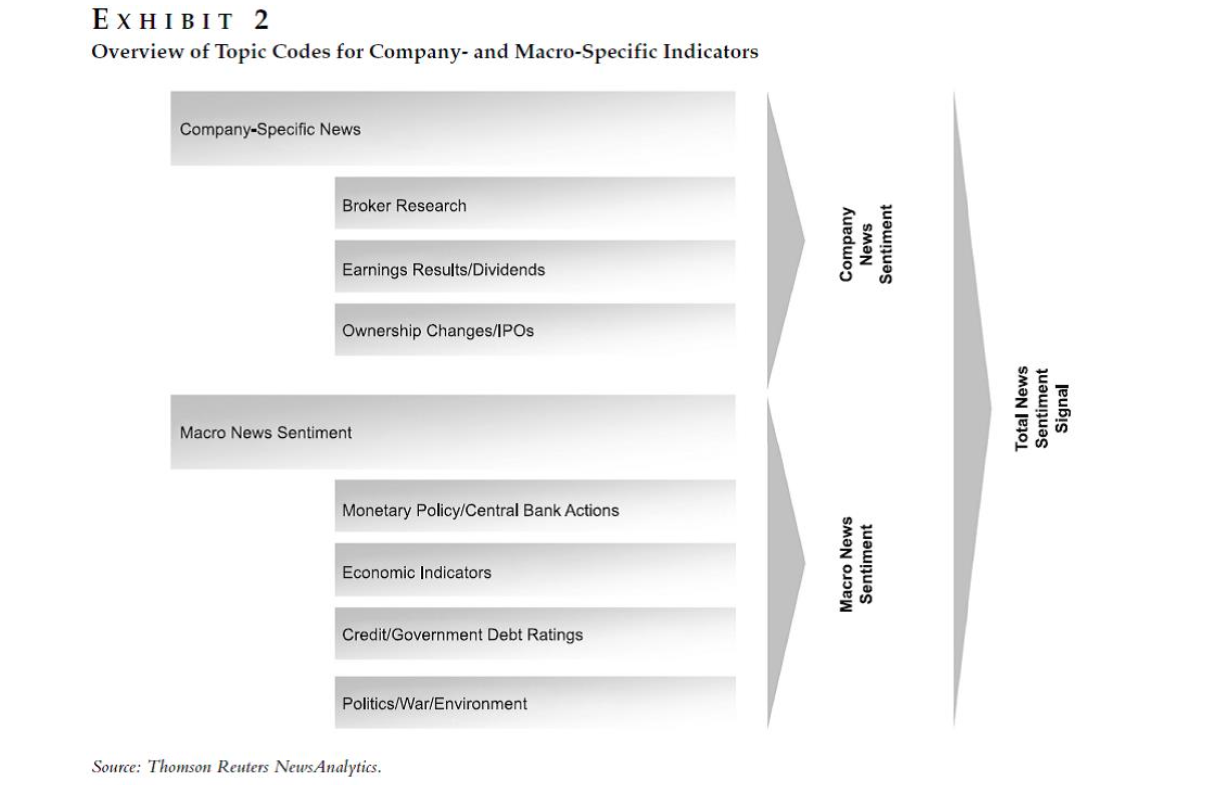
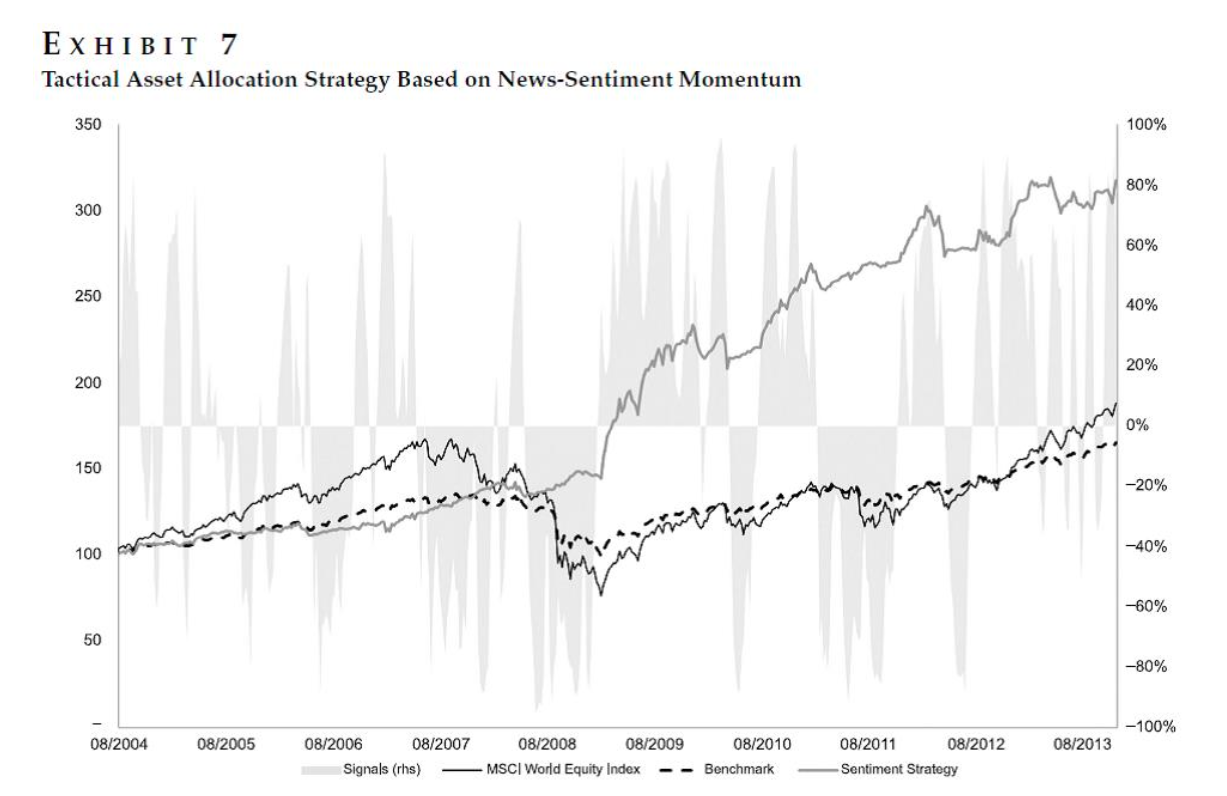
A good example is represented by the work of Uhl et al. in 2015, in the paper "What's in the News? Using News Sentiment Momentum for Tactical Asset Allocation" (Journal of Portfolio Management), who performed the following analysis:
- they obtained news sentiment analysis from Thomson Reuters News Analytics, where each story is linked to a sentiment that can be positive, neutral, or negative (1, 0, or -1);
- they aggregated news at the company and macro levels and created the sentiment momentum, defined as the recent change in sentiment;
- they smoothed the variable to make the signal less noisy;
- they invested in MSCI World equities if aggregate equity sentiment (momentum) was positive and in an investment-grade 3–5-year bond index otherwise, achieving a Sharpe ratio of 1.47.
The main findings, beyond the high Sharpe ratio, were:
- news diffuses slowly (prices don't fully absorb the information when it appears, and investors have limited attention);
- the selection of the smoothing parameter (strength) affects performance;
- change matters more than level, as sentiment levels carry persistent bias and some assets are always covered with more negative sentiment than others.
Seasonality
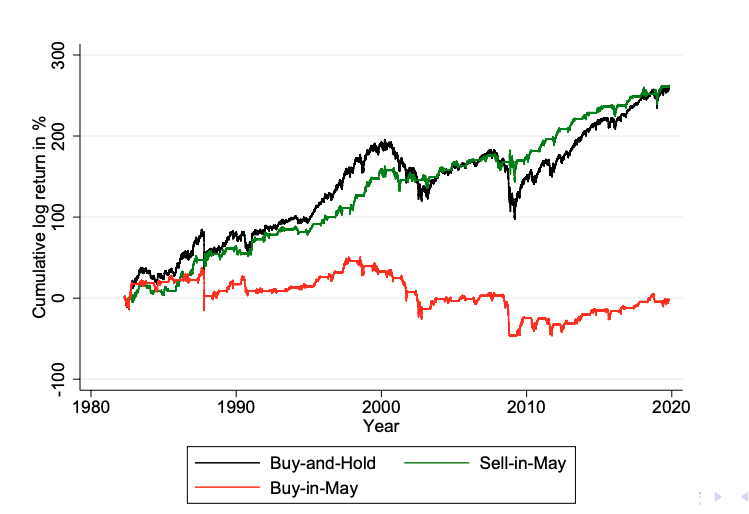
On Wall Street, there's the popular myth "sell in May and go away," referring to wealthy British merchants and aristocrats leaving London for their country estates during the summer. More generally, it says to invest in the stock market from late October to May and stay in cash from May to late October.
To investigate whether this pattern is present, we can easily use futures contracts since their percentage price change represents excess return. Take, for example, the 1982–2019 period and compare the following:
(Recall that the return of futures is , which is the return of the risky position over the risk-free rate. Also, note that futures indices provide clean data, take dividends and rolling into account, and are easy to short or leverage.)
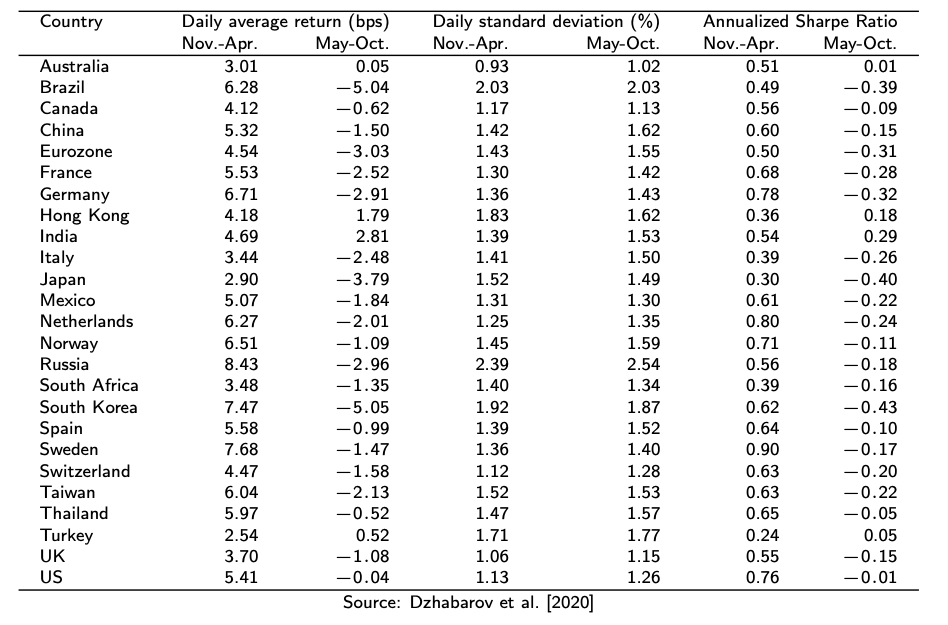
Furthermore, if we take a look at seasonal returns, we have the following:
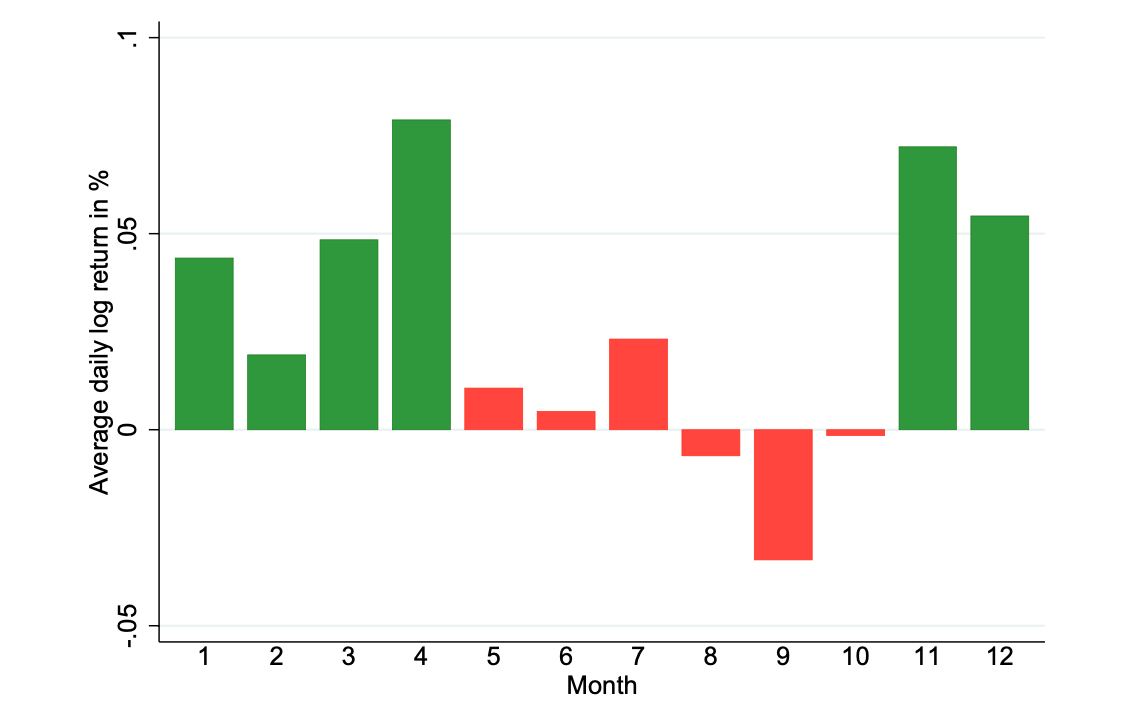
Furthermore, again, this effect is not present only in the US market, but rather in almost all countries. We also notice that, since winter months also show lower volatility, the Sharpe ratio from investing during winter is quite high.
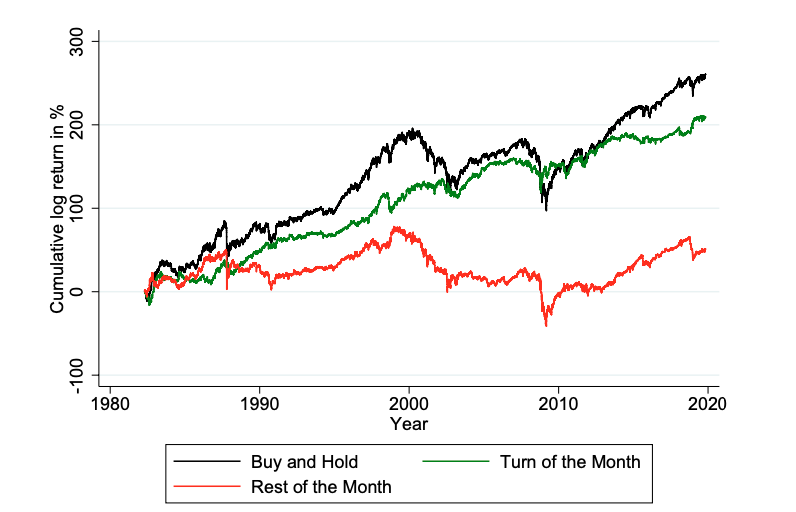
When looking at seasonality, we also notice the "turn-of-the-month" effect, which says that returns are much higher at the turn of the month than during the rest of the month. Again, we can easily test this using futures contracts during the 1982–2019 period:
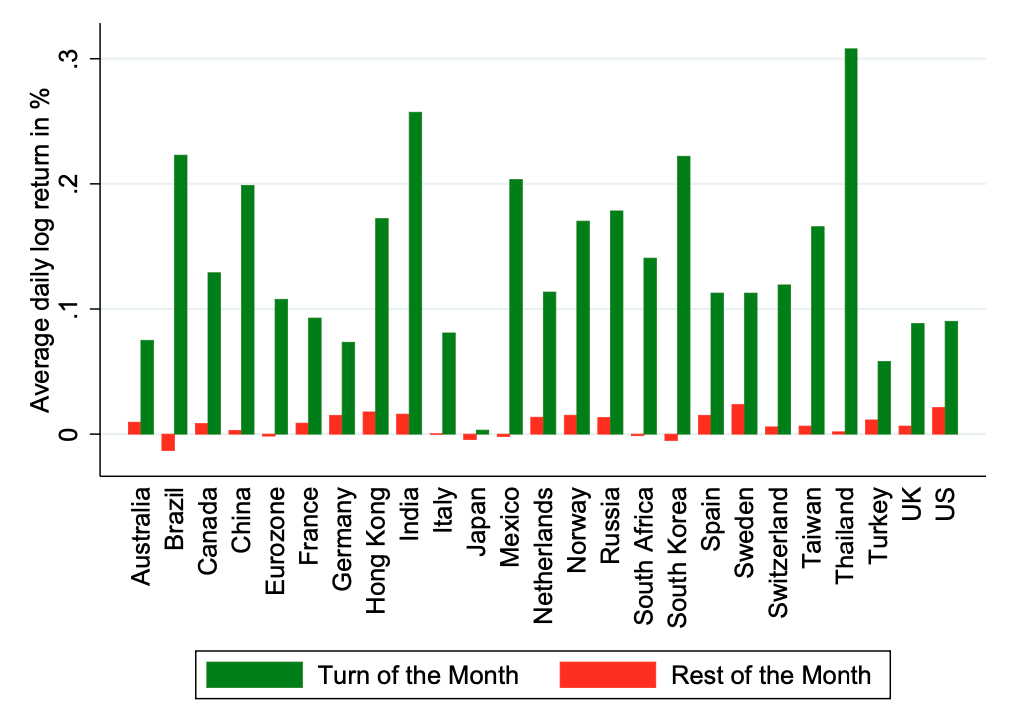
In particular, returns are higher during the first five and last five trading days of the month, and this is valid in almost all countries:

Furthermore, if we only include the first and last trading days of the month, we get a stronger result:
The Cross-Section of Expected Returns
The general idea of this section is to analyze the cross-section of expected returns to identify variables that help explain differences in expected returns across stocks.
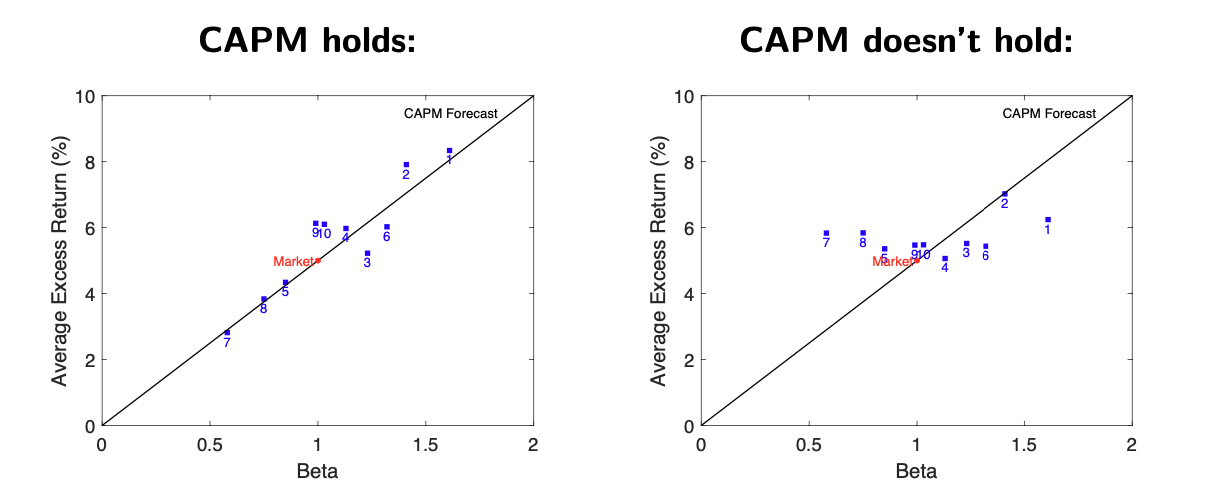
Typically, new factors are identified by comparing returns on assets (or portfolios) using some variable. For example, the CAPM predicts that market beta, defined as the covariance between the asset and the market portfolio divided by the variance of the market portfolio, should explain the cross-sectional variation in expected returns; expected returns should be driven by one single factor.
We can test this with a regression test, with the hypothesis that market-model alphas are jointly zero (i.e., stocks earn higher returns only by carrying more market risk, which translates into higher ).
In particular, for all assets , we can estimate the market model as:
and test the null hypothesis of the CAPM, i.e., for all . If this is not the case, implies that the asset is underpriced (as it "beats" the market), while implies the opposite.
Note that we could test each on its own, but with many assets, probably some of them will look significant by pure chance, so we must test if all the are zero at the same time; only in this way does the test take into account that the are correlated across assets.
Graphically, we can see the null hypothesis as follows:
Once an effect has been documented and we have tested the CAPM, we can ask ourselves if the differences we see in returns are caused by some other factor exposures (risk premia) or by mispricing, as a consequence of some investors' behaviors (slow processing of information, institutional constraints or frictions, behavioral anomalies, etc.). In the following lines, we therefore spend some time considering and diving deeper into some factors that have been documented to affect expected returns.
However, before we dive in, note that in the financial literature there is a large number of documented factors, but the majority of them come from data mining (p-hacking) and are not explained by any economic rationale. For the systematic investor, it is then important to differentiate between authentic and robust factors based on economic rationale, logic, and causation from redundant factors driven only by correlation. More on this topic can be found in the bestseller Navigating the Factor Zoo: The Science of Quantitative Investing by Michael Zhang, Tao Lu, and Chuan Shi.
Size and Value FactorsBanz, in his 1981 paper titled "The Relationship Between Return and Market Value of Common Stocks" (Journal of Financial Economics), found differences in average returns between stocks with large and small market capitalization.
Similarly, Stattman in 1980 in "Book Values and Stock Returns" (The Chicago MBA: A Journal of Selected Papers) and Rosenberg et al. in 1985 in "Persuasive Evidence of Market Inefficiency" (Journal of Portfolio Management) found that average returns on US stocks are positively correlated with the ratio of a company's book value of common equity to its market value, defined as the B/M ratio.
Lastly, Fama and French, in 1992, 1993, and 1996, in their papers "The Cross-Section of Expected Stock Returns" (Journal of Finance, 1992), "Common Risk Factors in the Returns on Stocks and Bonds" (Journal of Financial Economics, 1993), and "Multifactor Explanations of Asset Pricing Anomalies" (Journal of Finance, 1996), combined size and value factors and expanded the CAPM to explain the cross-section of expected stock returns, in particular:
- at a given , they sorted stocks according to their B/M ratio;
- they distinguished stocks with high B/M as value stocks and those with low B/M as growth stocks, so these names were defined relative to other stocks in the cross-section, not in absolute terms;
- similarly, they sorted stocks based on their market capitalization;
- they then distinguished them into Small and Big stocks;
- with these two dimensions, they constructed portfolios and investigated their expected returns.
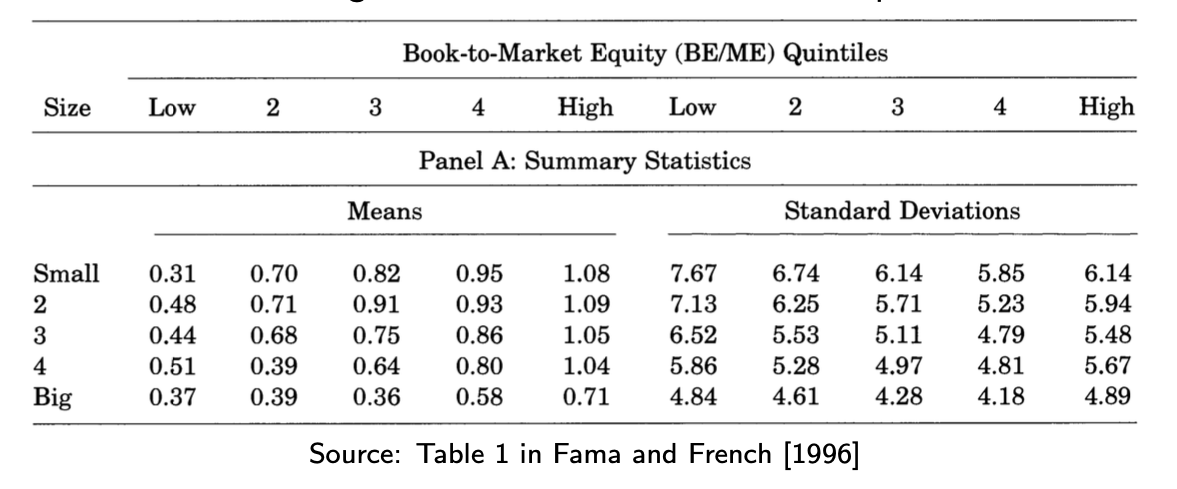
They then found that:
- value stocks have higher average returns than growth stocks;
- small stocks have higher average returns than big stocks.
However, they noticed that these differences were not reflected in differences in the market , so the higher return could not be explained by the CAPM.
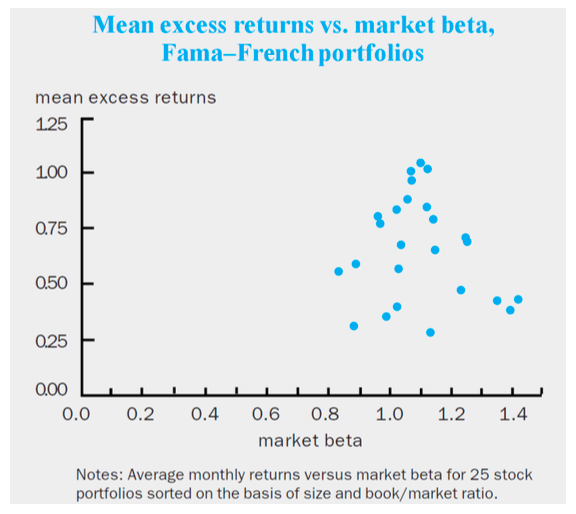
In order then to explain the cross-sectional variation in returns, Fama and French constructed size and value factors as follows:
- sort stocks independently by market cap and by B/M ratio into portfolios
- compute their returns, with each portfolio value-weighted
- define the small minus big factor as:
- define the value factor (High minus low) as:
Note that the factors are self-financing portfolios, i.e. the long part is financed by the short part; in particular, we indeed have:
- for the size factor, we're investing in small caps and financing the positions by shorting large caps
- for the value factor, we're investing long in value stocks and financing the positions by shorting growth stocks
Therefore, factor returns are already excess returns and there's no need to subtract the riskless asset return.
For practical applications: on French's web page there are historical data and detailed descriptions of many factors! Access everything here.
Based on these factors, the authors construct a 3-factor model: where:
- is the excess return of asset or portfolio ,
- is the excess return of the market,
- and are the size and value factor returns, respectively, represents the model’s mispricing, and
- is a mean-zero error term.
From this model, pricing errors are small on the tested portfolios, averaging per month.
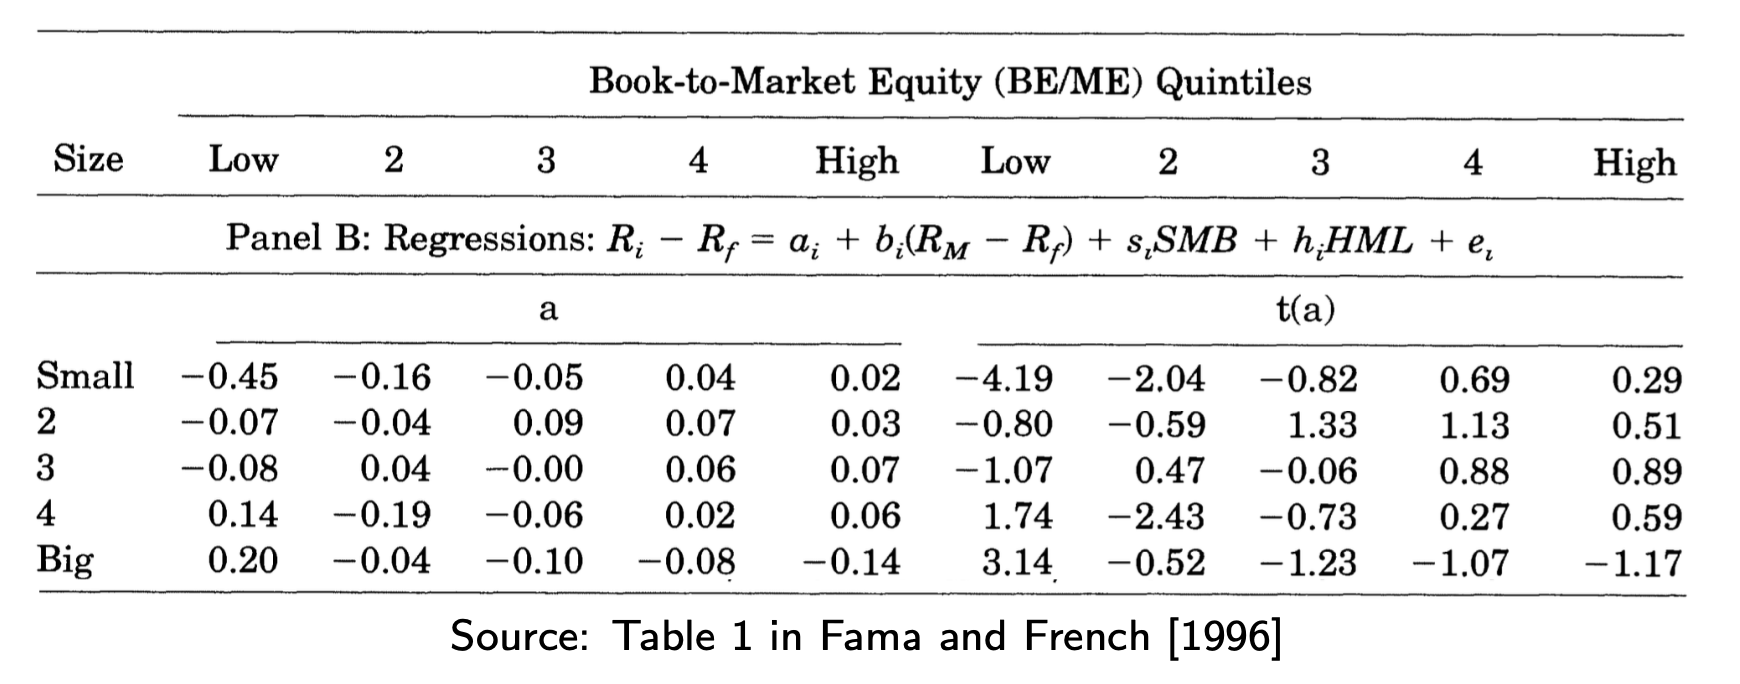
Furthermore, note that the tested portfolios' market betas are quite similar, so the difference lies mainly in the exposure to value and factors, as and vary a lot.
We can now infer that the profitability of a factor can represent its risk premium (compensation for risk) or mispricing by the investors. For example, the positive average returns on the value factor could be caused by a recession premium reflecting the pro-cyclical nature of value stocks or by the undervaluation of value firms due to behavioral reasons.
Empirically, returns of the HML factor forecast changes in the Chicago Fed National Activity Index, consistent with a risk-based explanation.
Profitability and Investment Factors
If we go a little bit further in history... in 2015, with their famous paper "A Five-Factor Asset Pricing Model" (Journal of Financial Economics), Fama and French extended their 3-factor model to a 5-factor model by adding profitability and investment factors, so the model is:
where and are the returns of the following factors:
- profitability factor (robust minus weak profitability), sorting companies based on
- Investment factor (conservative minus aggressive portfolios), sorting companies based on the percentage growth in total assets.
As we should expect, intercepts are much smaller when using 5 factors than when using the previous model (so it performs better in terms of mispricing is negligible). In particular, the profitability factor shows that firms with operating profitability have higher results. Similarly, firms that invest little have higher average returns compared to firms that do less.
However, note that the profitability and investment factors may overlap with the value factor; we could indeed explain the premium of the value factor by its exposure to the other factors, making the value factor redundant.
Momentum
Jegadeesh and Titman in 1993 and 2001, in their papers "Returns to Buying Winners and Selling Losers: Implications for Stock Market Efficiency" (Journal of Finance, 1993) and "Profitability of Momentum Strategies: An Evaluation of Alternative Explanations" (Journal of Finance, 2001), studied a strategy whose fundamental idea was going long on stocks that performed well in the previous 3–12 months and shorting the others in the same period, with the intuition that firms with previous high returns keep performing well and the same applies to the ones with lower returns, with a reversal after about 12 months.
This strategy can be called momentum and its returns are not explained by the Fama and French 5-factor models.
In particular, note that momentum is performing particularly well in November and December and it reverses in January, likely because of window-dressing and tax-loss selling at the end of the year.
We could interpret a momentum strategy in two similar ways:
- we buy top performers and short bottom performers (so based on the cross-sectional momentum, i.e. relative returns to the asset class)
- we buy assets with positive returns and short ones with negative returns (so based on their absolute value)
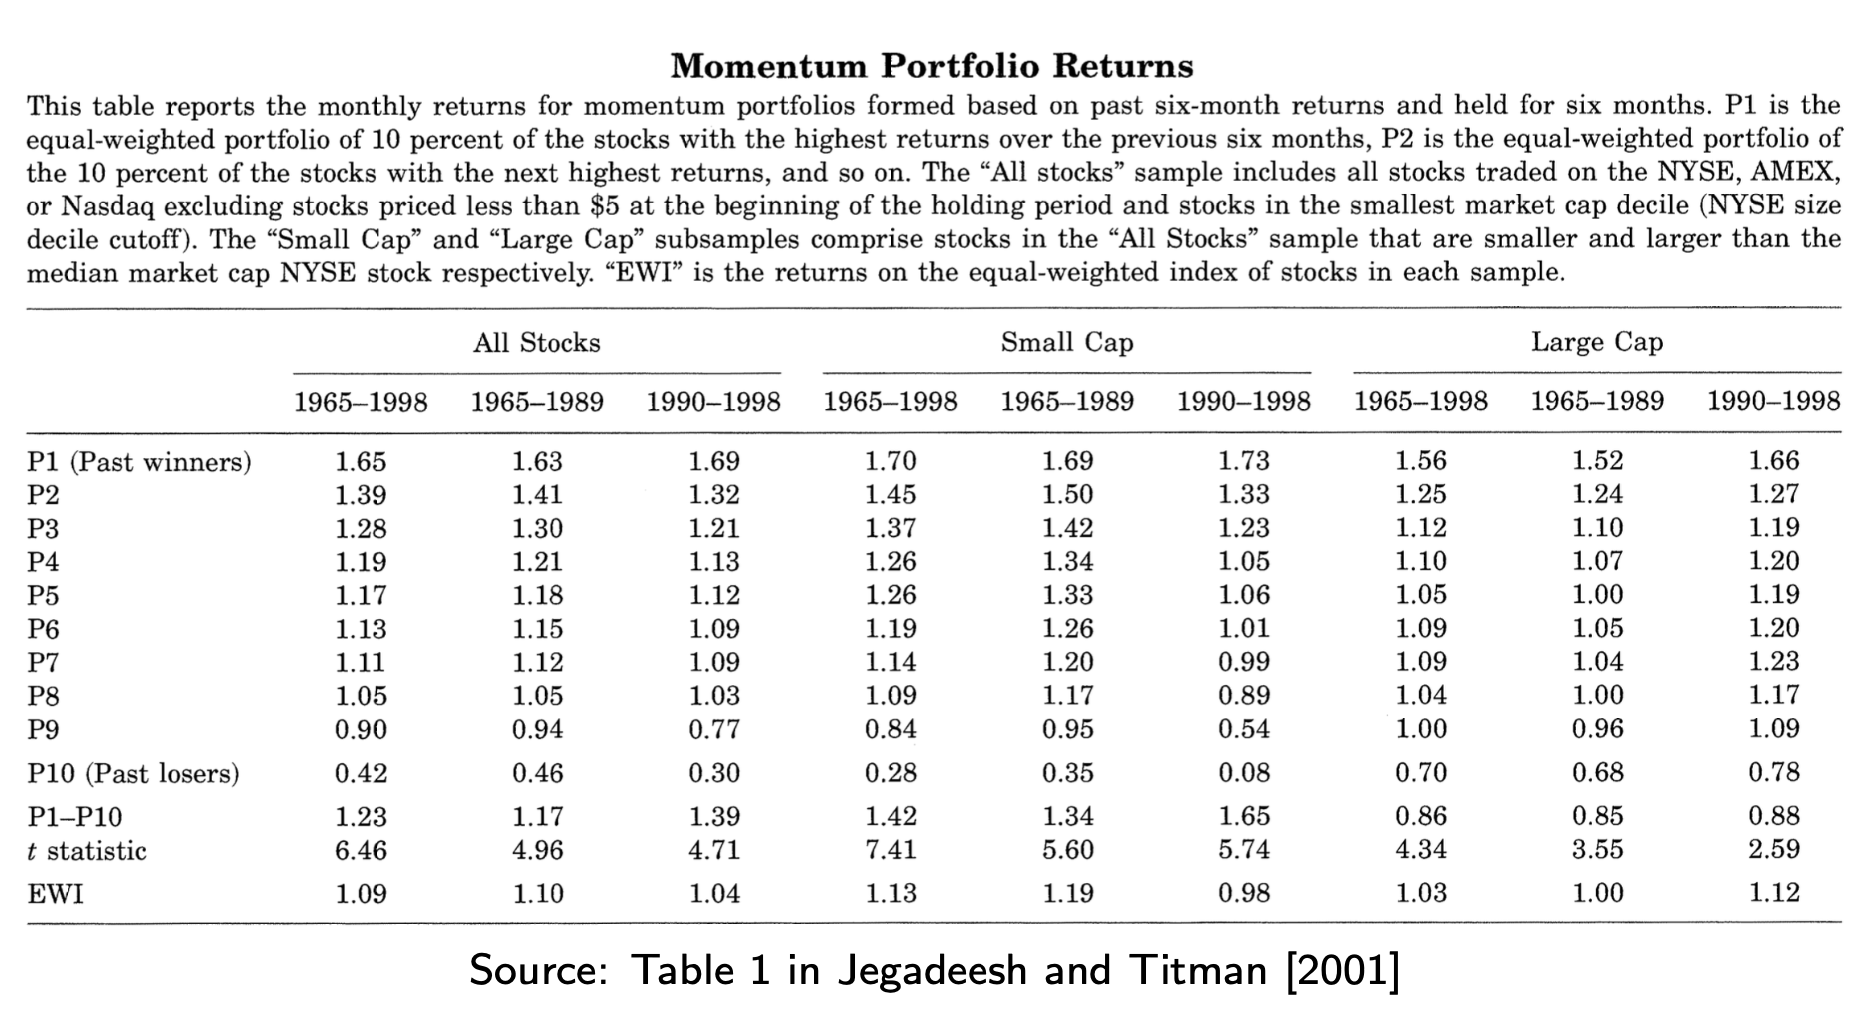
Note that momentum is NOT driven by differences in unconditional expected returns, but by under- and overreaction to firm-specific information that is processed slowly by investors (i.e. trends take time to be born, live and end) and the subsequent overreaction of the investors once the trend is created and they want to ride this trend.
Momentum can indeed achieve good performance but its returns are negatively skewed, i.e. it shows infrequent but large crashes; and its turnover is high large transaction costs.
Also, Novy-Marx [2012], in the paper "Is Momentum Really Momentum?" (Journal of Financial Economics), shows that intermediate-horizon past performance (measured over the period from 12 to seven months prior inclusive) predicts returns better than recent past performance (measured over the period from six to two months prior inclusive).
Regarding its relation with the other factors, we see that momentum is negatively correlated with the value factor and, in a given country, the presence of momentum (or value) in an asset class is positively correlated with the presence of momentum (or value) in another asset class.
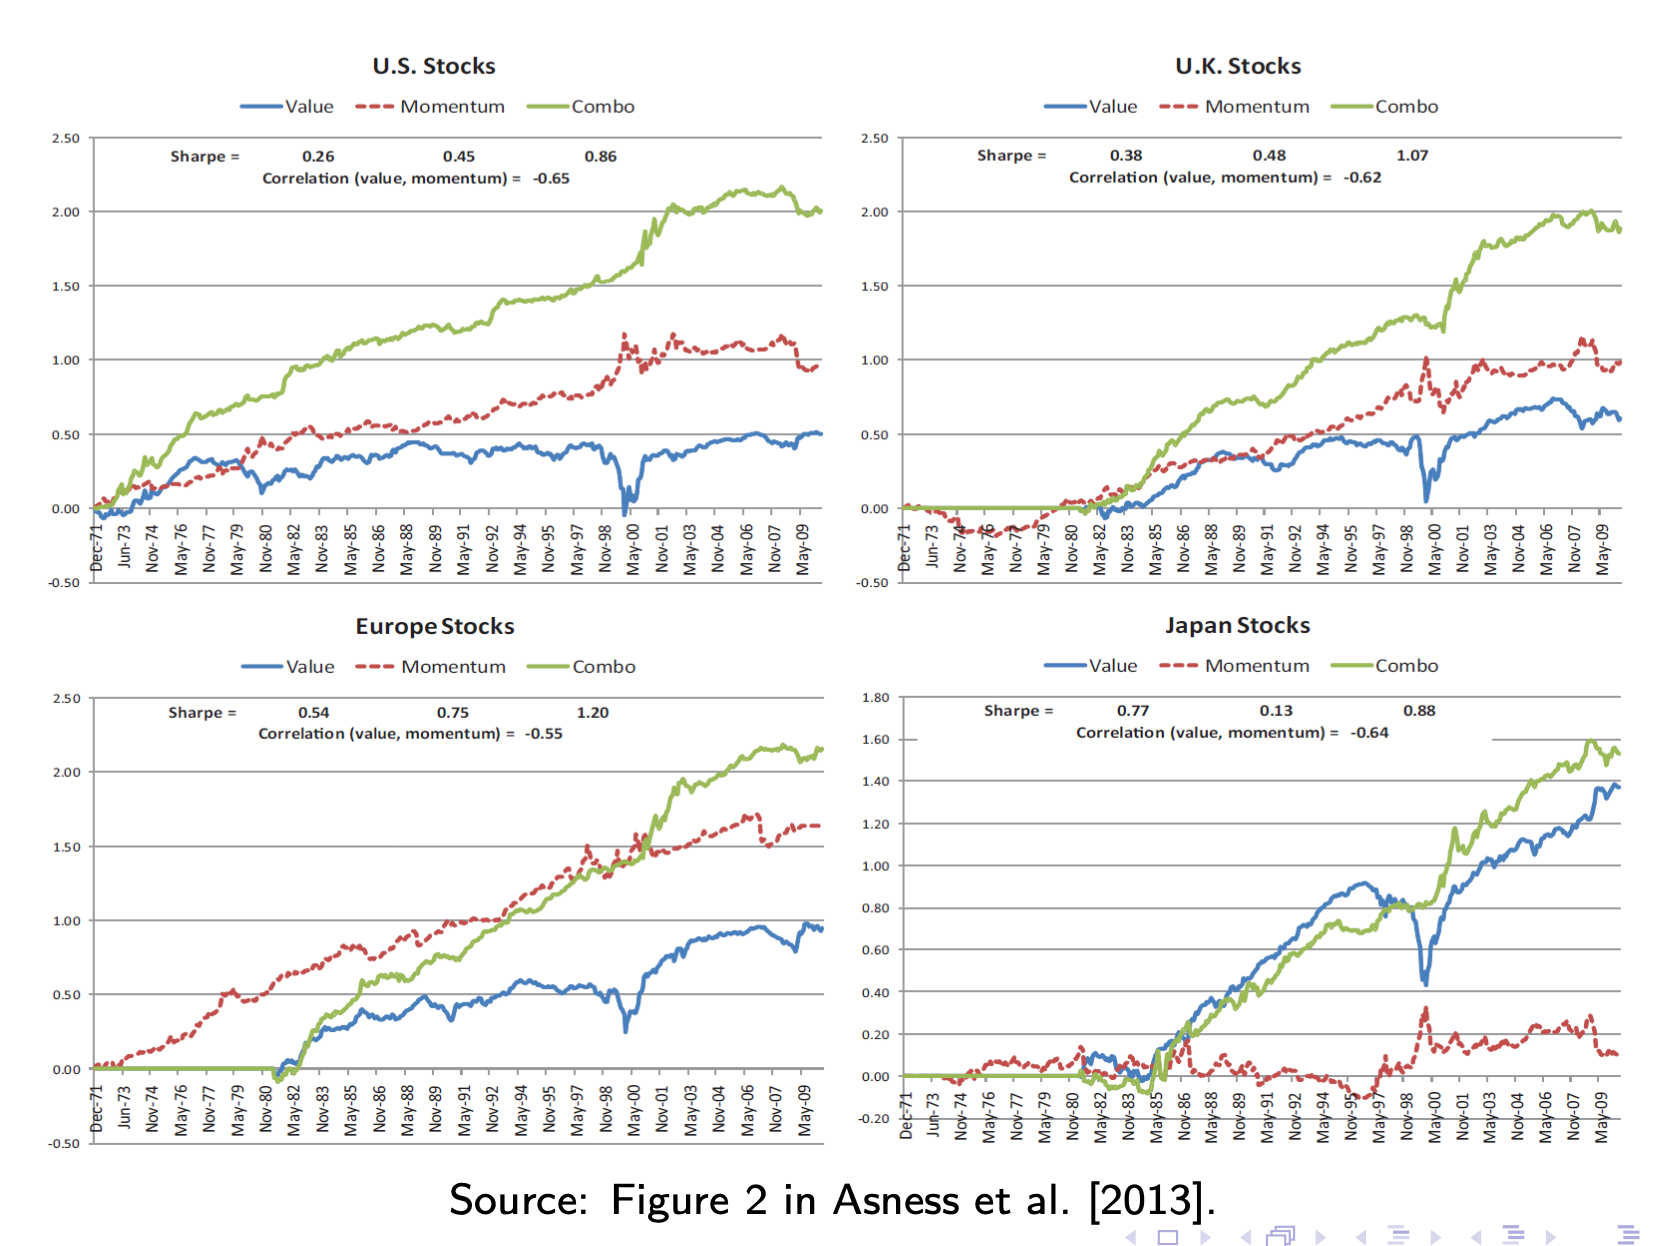
In terms of performance, momentum has a very large Sharpe ratio, but, because of this negative skew and sudden crashes, there's still ongoing research into dynamic momentum strategies to decrease this asymmetric and negative aspect.
In particular, Barroso and Santa-Clara in 2015, in their paper titled "Momentum Has Its Moments" (Journal of Financial Economics), found that momentum's Sharpe ratio is much lower after periods with high volatility. If we indeed build quintiles based on the past six months' volatility, we see the following pattern:
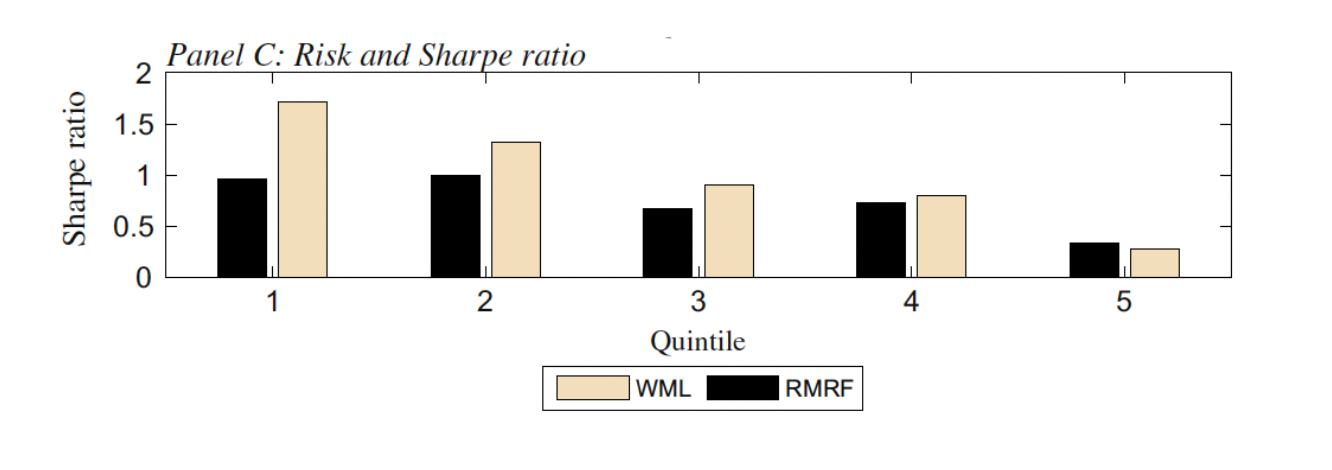
So they scaled the investment in the momentum portfolio based on the ratio of target volatility to the realized volatility of daily momentum returns in the previous six months, using . Doing so, we see that between 1927 and 2011 this scaling increases the Sharpe ratio from 0.53 to 0.97 and reduces skewness.
Furthermore, Daniel and Moskowitz in 2016, in the paper "Momentum Crashes" (Journal of Financial Economics), incorporate expected return and risk separately in the weight allocation. In particular, using regressions, they found that momentum returns are particularly poor during bear markets with high volatility, when:
- there has been a constant/steady market decline
- risk ( variance of daily market returns in the previous 16 days) is high.
In this case, a dynamic momentum strategy scaled the investment in the momentum portfolio based on its conditional expected return and variance, considering
achieving a Sharpe ratio double that of the initial static momentum strategy (with in-sample parameters...)
Low Beta
We see that, historically, the security market line is flatter than predicted by the CAPM.
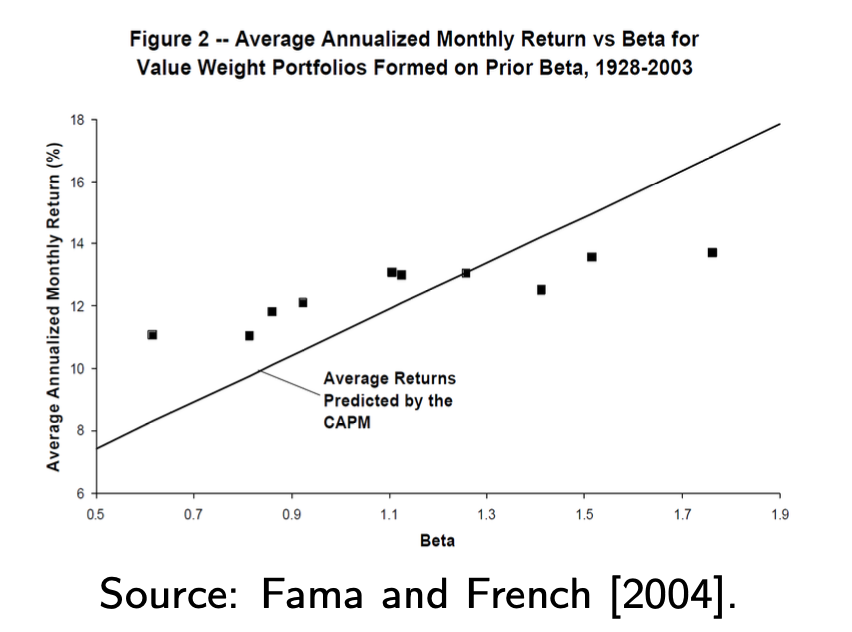
This can be explained by the fact that many (institutional) investors face leverage constraints. For example, US regulations constrain leverage at 2:1 and brokers generally do not allow more than 4:1 intraday leverage (hey! I've written a lot about leverage here!).
Therefore, in order to achieve higher returns, investors facing this constraint purchase high-\beta assets, causing them to be overpriced. On the other hand, unconstrained investors can achieve good returns by taking leveraged positions in underpriced low-\beta assets.
The betting-against-beta factor (BAB), introduced by Frazzini and Pedersen in the paper "Betting Against Beta" (Journal of Financial Economics, 2014), tries to capture this by going long on low-\beta assets and short on high-\beta assets, generating high returns and Sharpe ratios.
The BAB, furthermore, is constructed to be market-neutral by leveraging up (scaling up) low-beta assets to a beta of 1 and then de-leveraging (scaling down) high-beta assets to a beta of 1, so the factor return is given by:
However, note that the BAB portfolio is not self-financed; therefore, the riskless rate must be subtracted from the short and long positions to obtain the excess return.
Also, note that the BAB return cannot be explained by other common factors (otherwise it would be useless!), and the profitability of BAB holds across different asset classes and countries.
Buffett's Factor Exposure
Frazzini et al., in their 2018 paper titled "Buffett's Alpha" (Financial Analysts Journal) studied how Warren Buffett has been investing and how his performance is related to factor exposure.
Their major finding is that Buffett is largely positively correlated with the market, value stocks, low-beta assets, and the quality factor, with a leverage ratio of .
In this context, quality stocks are related to the "quality factor", constituted by Asness and the previous work of Piotroski.
In particular, Piotroski, in his 2000 paper "Value Investing: The Use of Historical Financial Statement Information to Separate Winners from Losers" (Journal of Accounting Research), created an indicator to distinguish high-quality stocks from low-quality stocks, using only accounting information. The Piotroski F-Score is calculated by evaluating financial strength using scores from 0 to 9 across nine signals in the profitability, leverage and liquidity, and operating-efficiency categories. A score between 8 and 9 indicates strong financial quality, while 0–2 indicates very weak quality.
Asness et al. in 2019, in the paper "Quality Minus Junk" (Review of Accounting Studies), then created the QMJ (quality minus junk) factor, which goes long on firms with strong profitability, high growth, and low risk, and short on the opposites.
Note that Frazzini, in the Buffett paper, used a slightly different version, but the intuition is unchanged.
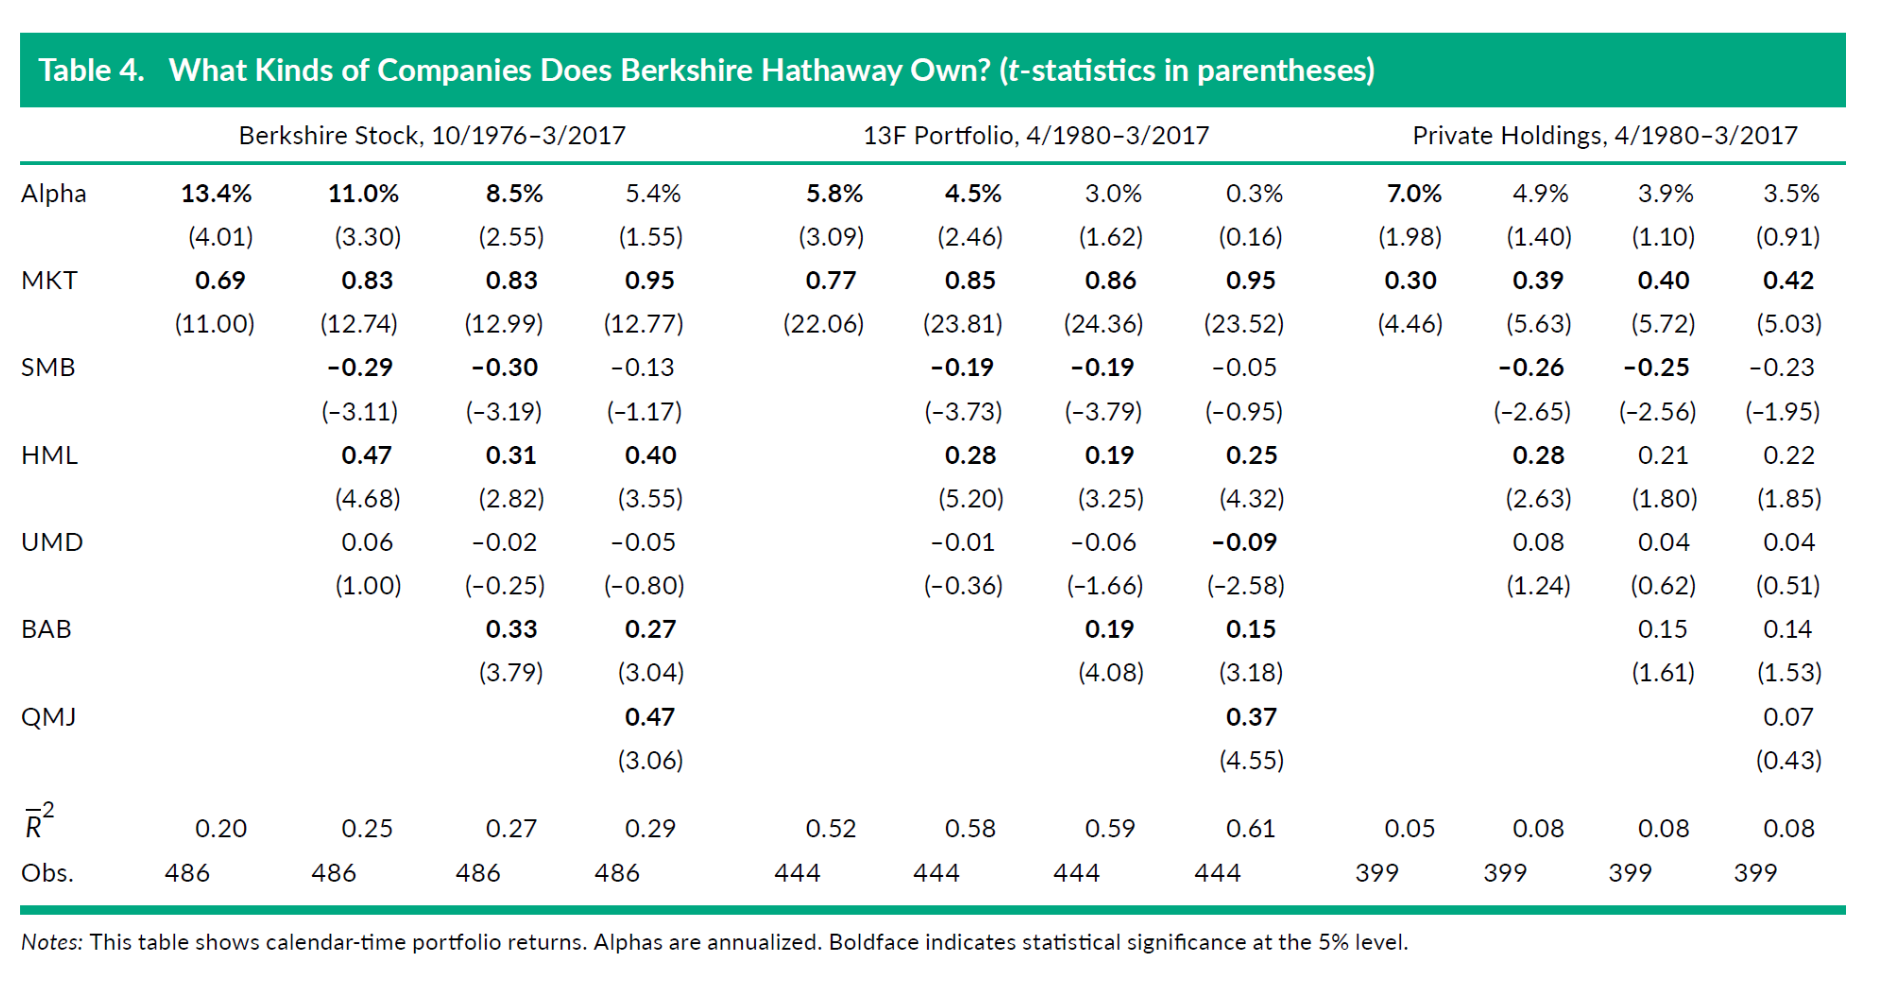
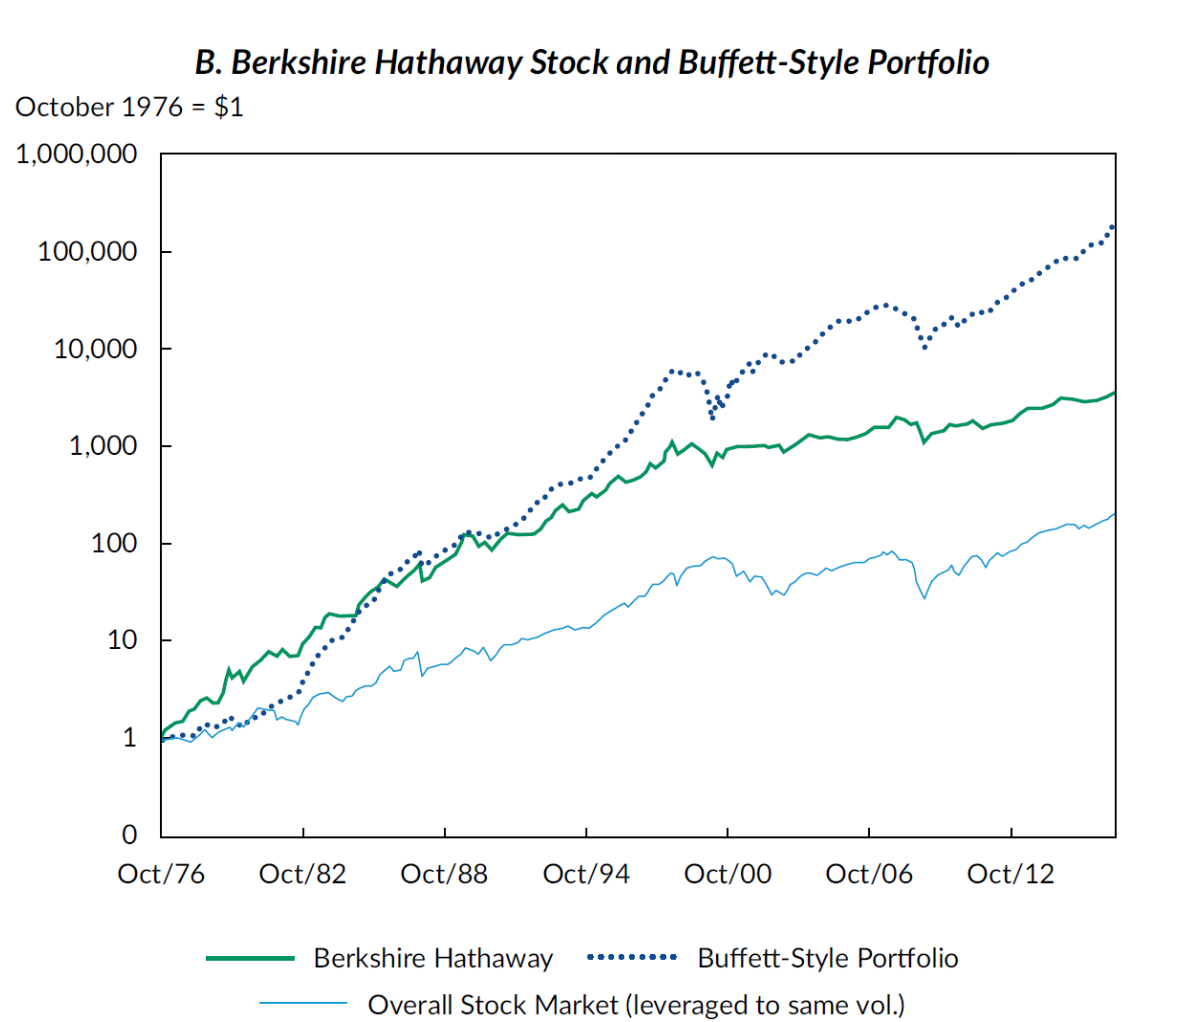
Furthermore, Frazzini reproduced Buffett's investment philosophy by "fictionally" investing in the academic factors and rescaling them to have the same volatility as Berkshire stock returns, as shown below:
Statistical Significance Issues
As briefly reported at the beginning of the chapter, while mentioning Navigating the Factor Zoo (recommended!), a large number of factors have been studied throughout history. However, many result from repetitive data mining.
Harvey et al., in their 2016 paper "...and the Cross-Section of Expected Returns" (Review of Financial Studies), claimed that, for a factor to be considered relevant, a t-statistic much higher than 2 should be achieved, so, according to them, most of the factors found in the financial literature are most likely false. Nevertheless, they still attribute relevance and statistical significance to the MKT, SMB, HML, MOM, and BAB factors.
We can see in the following graph the required t-statistics over time for a factor to be considered relevant.
Bonds, the Expectation Hypothesis and Bond Risk Premium
When working with discount or zero-coupon bonds, we can denote the price at time of an -year bond by and the corresponding log bond price by .
We can interpret coupon bonds as a portfolio of zero-coupon bonds. Indeed, if we denote by the coupon bond's cash flow in periods, it can be written as:
We can define the gross yield (i.e. the annualized return from holding the bond to maturity) on a discount bond with years to maturity as the rate that solves
and the continuously compounded yield (log yield) as
Note that the continuously compounded rate uses a linear relationship between the log price and the maturity, and this makes yields additive over time.
We can now define the forward rate as the rate at which you can contract today to lend or borrow in the future. We denote the discrete and continuously compounded forward rates for a loan from time to time by and .
From the no-arbitrage condition, we have:
Then, we can express bond prices as their discounted present value using forward rates:
We can now define the realized discrete and continuously compounded returns from holding an -period bond, from to as:
and note the particular case for which the return from holding a one-period bond is just its yield:
We denote the excess log returns from holding an -period bond by:
which can be decomposed into the initial yield spread and the change in the bond's log yield from period to period , scaled by its remaining duration. In formulas, we have:
For example, suppose that the 1-year log yield is 1% and we purchase a 10-year bond at 2%. Suppose also that one year later the 9-year yield is 1.8%, so the excess log return from holding the bond is:
Three Basic Questions when investing in Bonds
Note that yields are just a convenient way to describe zero-coupon bond prices, so if we can describe the evolution of yields, we can also model bond returns for portfolio construction and risk management.
In general, when evaluating the yield, we should start with the following questions:
- Why do interest rates move?
- Why do yields differ across maturities?
- Why does the yield spread vary over time?
We now start to understand the first point. Firstly, recall that yields are characterized by a dominant level factor shifting yields of all maturities up and down. Recall also that short rates are set by the central bank, taking macroeconomic factors (with particular focus on unemployment and expected inflation) into account.
In particular, the central bank sets a target for the overnight interbank rate (Fed funds rate or ECB deposit rate), steering the market rate toward the target rate using:
- interest paid on reserves (deposit rate)
- a ceiling on the rate for lending facilities (money lent to banks overnight at a fixed rate)
- open market operations (buying or selling securities to change the supply of reserves)
The rate is chosen, with a good approximation thanks to the Taylor rule, using this formula:
where:
- is the nominal policy rate, i.e., the rate the central bank sets at time .
- is the neutral real rate, i.e., the real interest rate that neither stimulates nor cools the economy (usually estimated at about 2%).
- is the current inflation rate, which is added to .
- is the inflation target (more or less 2% for the Fed and the ECB).
- is how strongly the bank reacts to the inflation gap.
- The output gap is the percentage difference between actual and potential GDP, positive in a boom and negative in a slump, and it is linked to unemployment (a negative gap implies high unemployment).
- is how strongly the bank reacts to the output gap.
If inflation is above the target, interest rates are raised to decrease demand; if unemployment is high (i.e., the output gap is negative), rates are cut to stimulate the economy.
Then, the long yield curve is the average expected future short rates plus a term premium for the risk of holding bonds. In particular, if markets expect the bank to keep rates high, yields at all maturities rise together (the level factor). However, quantitative easing or tightening (buying or selling long bonds directly), guidance and communication, and market demand and supply can also influence the long yield.
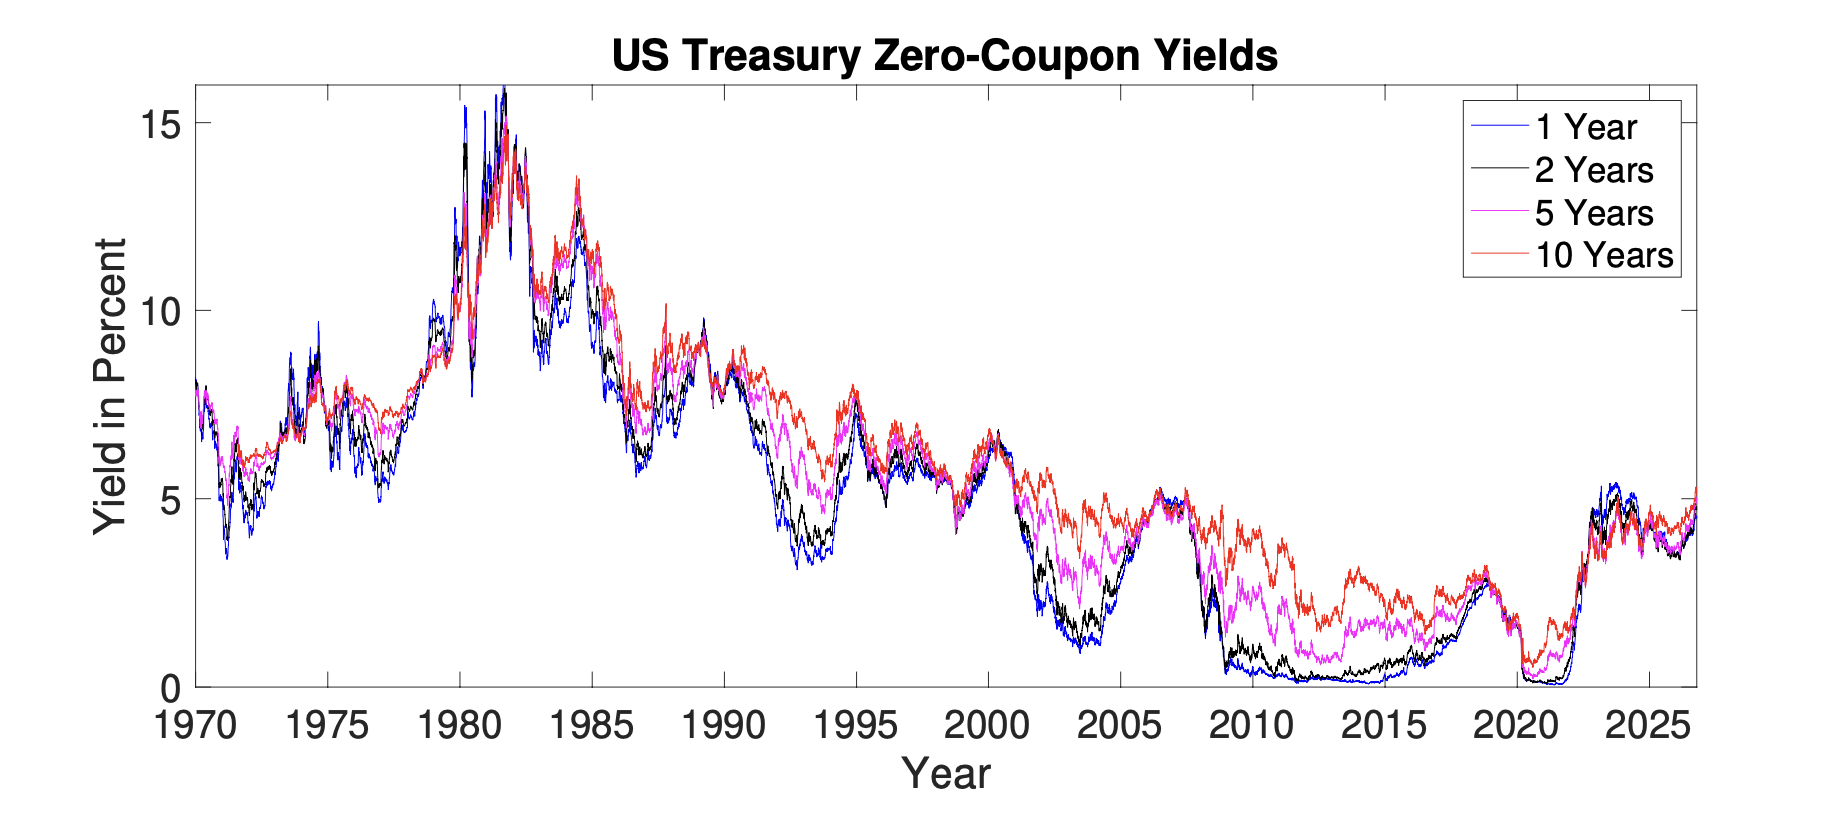
The yield curve is a plot of yields of zero-coupon bonds as a function of their maturities, also called the term structure of interest rates.
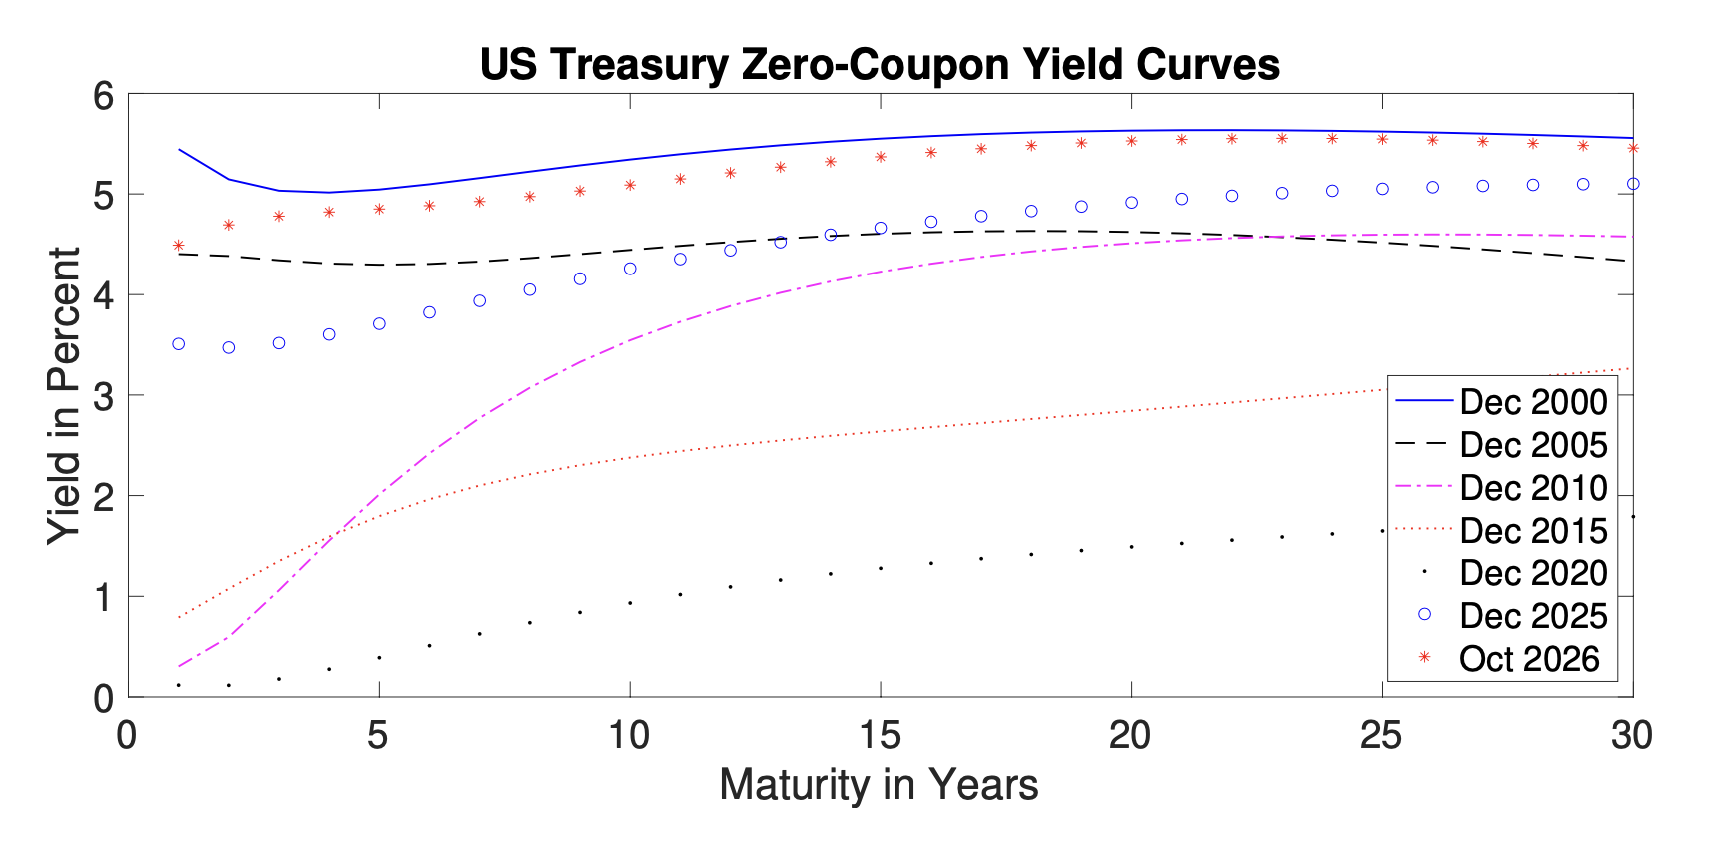
Similarly, the yield spread (term premium or term spread) represents the slope of the yield curve, i.e., the difference between long and short yields. If the
During recessions (in grey in the plot below), we usually see a steeper yield curve (central banks usually cut short-term rates, but the long yield falls less because investors expect the economy to recover and rates to rise again, and, since risk is higher, the term premium is also large), while during expansions the curve usually flattens or even inverts (as the economy grows, inflation rises and the central bank raises the short rate, but long yields rise less since investors expect the tightening to be temporary).
Note also that yield curve inversions typically occur right before a recession, since an inverted curve means that the market expects future short rates to be lower, usually because the central bank is holding rates high enough to slow down the economy.